Tag: stubborn fanatic

  • The law I cannot read · กฎหมายที่ผมอ่านไม่ออก

    The law I cannot read · กฎหมายที่ผมอ่านไม่ออก

    The law I cannot read

    I have legal interests in Thailand, and I cannot read Thai.

    That is an awkward position for a lawyer. Thailand’s statutes are published in Thai, and the Thai text is the law. Anything in English is somebody’s reading of it. For the Codes that govern property, family and succession, the Thai government’s own legal drafting office holds no English text at all. I checked, and how I checked is part of this post.

    So I built a second law library on my own computer. The first one, of Indian statutes and judgments, is a separate project. This one holds Thai law in Thai, with every line of English labelled by how far it can be trusted, and it answers a search in a fraction of a second.

    I built it with Claude, Anthropic’s AI model, working as an agent: it could run programs on my computer and use my Chrome browser, under rules I set. I made the decisions. The scripts and most of the investigation came from the model, and so did a good number of the mistakes. The work started on 4 September 2026; most of it ran in the last week of September.

    One thing to say before anything else: I am an Indian advocate, not a Thai lawyer. This is a post about building a research tool, not advice on Thai law. There is a fuller note at the end.

    Every English word gets a label

    The first decision was a rule about English.

    Thailand is a civil law country. Thai courts are not formally bound by earlier decisions, the Supreme Court’s included, though those decisions carry weight. The statute book matters more than case law, and the statute book is Thai. If I am going to rely on any of this, every English sentence has to say where it came from.

    So there are four tiers:

    T1  Thai official text, or English the agency published as part of the instrument
    T2  English published by a Thai agency, marked unofficial
    T3  third-party English: commercial translations, law firm sites
    T4  machine output, ours: for finding and reading only, never quoted, never cited

    Every text file carries a tier: line in its header, and the search tool prints the tier beside every result. Machine English comes out as T4 machine translation - NEVER quote or cite, in capitals, every time. That label is what stops a fluent sentence from turning into a citation.

    Finding the statute book

    The Office of the Council of State publishes the official consolidated text of Thai laws. Its old address, krisdika.go.th, no longer served it; the office had moved to ocs.go.th.

    The new site’s search page is backed by a form-encoded endpoint, POST /searchlaw/indexs/list_table_search. Two things stood between it and a clean list.

    The first was TLS. The server does not send its intermediate certificate. A browser fetches the missing certificate itself; Python’s requests does not, and fails. Setting verify=False would have silenced the error by switching the check off. The fix used instead was truststore, which hands verification to Windows’ own certificate chain building, and Windows can find the missing intermediate. The check still happens.

    The second was a filter. The site’s own search page sends the parameter query[lawCategoryName] with the value 1B,1C. Sent that way, the index hid 7 of 147 records. Sent empty, all 147 came back. I would not have known without counting both ways.

    That gave titles and PDFs, not text. The text sits behind a viewer, an Angular single-page app, and five guessed endpoints returned 404. What worked was opening the viewer in a browser and reading how the page itself asks the server for a law, from its network traffic and its JavaScript bundle. The viewer uses a public JSON endpoint:

    POST https://searchlaw.ocs.go.th/ocs-api/public/doc/getLawDoc
    Content-Type: application/json
    
    { "reqHeader": { ...request id, channel, timestamp, service name... },
      "reqBody":   { "timelineId": "<id from the index>", "isTransEng": false,
                     "sectionIds": [], "sectionAndExplains": [] } }

    What comes back is structured: each section with its number, label and HTML content, plus every version of that law. For the Civil and Commercial Code that was 2,254 entries and 605,706 characters, in force from 25 March 2025. File downloads on the same site go through a route that needs a token the viewer holds. The token was never read or reused: the English PDFs mentioned below were saved through the viewer’s own download button, as any reader would save them.

    The English that was not there

    The same request has a flag, isTransEng. Set to true, it asks for English.

    For all eight Thai Codes, the answer was SUCCESS with zero sections. The system knows the English names of the Codes. It holds none of their English text.

    There was one exception. The Civil and Commercial Code’s timeline has 73 versions, and one of them, the original 1925 text, is marked as having a translation: a 242 KB file. For a week the working assumption was that this was an English translation of the 1925 Code. When the file came down and was read, its title page said otherwise. It is the Act Amending the Civil and Commercial Code (No. 20), B.E. 2557 (2014): one amending Act, filed against the original version.

    The note was corrected with the date of the correction, and the earlier reading left on record. A timeline entry tells you a file exists. Only the file tells you what it is.

    The Council of State does hold English for other laws, and 70 such PDFs, covering 57 laws, are now in the library. They are T2, and they say on their face that the Thai is the sole authority. Many turned out to be amending Acts rather than the main Act, which is one more reason the library reads the Thai consolidation first.

    A section 2 that appeared 36 times

    With the endpoint working, the eight Codes came down as structured text: 5,526 entries, of which 4,453 are numbered provisions. Then the counting started, and the counting is where the bugs were.

    Section 2 appeared 36 times in the Civil and Commercial Code file. Each Code’s file carries the Acts that amended it, appended at the end, and each of those Acts numbers its own sections from 1. Left as it was, a search for section 2 would find 36 candidates and one of them would be right. Every entry now carries a flag saying whether it belongs to the Code itself. That is how the 2,254 entries in the Civil and Commercial Code file come down to its 1,850 provisions; the rest are headings and the appended Acts.

    Some of the others:

    • The Land Code has eight entries in a row all labelled section 105. They are 105, 105 bis, ter and on to octies. The label field cuts the number short, so the real reference is parsed from the text.
    • The same ordinal is spelled two ways: อัฎฐ with ฎ in the Civil Procedure Code, อัฏฐ with ฏ in the Land Code.
    • The site served escaped HTML comments, &lt;!--[endif]--&gt;, which only became comments after unescaping, so the comment-stripper never saw them. The selftest had passed because its fixture used a real comment: it was written from the fix, not from the data.

    Once all of these were fixed, no reference in any of the eight Codes appeared twice.

    When a repealed law is still current

    Each version in a law’s timeline carries a stateId. 01 looked like “in force” and 00 like “superseded”.

    Of the 652 index rows whose titles carry the repeal marker (ยกเลิก), 638 sit at 01. The last version of a repealed law is still that law’s current version. So repeal is read from the title marker, never from the state.

    A probe on 24 September found a third state, 02: published but not yet in force, with a fifth version type, a future consolidation showing the law as it will read once a pending amendment starts. On 30 September that turned up a trap. A value-added tax decree showed a future consolidation in force from 1 October 2026, and it left out a separate amending decree of the same date that keeps the reduced rate for another year. Read alone, the future text would have given the wrong rate. The library now holds the amending decree separately and flags any future version that matches the current one.

    That same day the whole library was checked against the Council of State: 837 timeline entries under the parent laws held, and all 773 laws unchanged since they were fetched. The consolidations themselves can trail behind amendments. The Revenue Code’s latest consolidation on the site is dated 9 November 2021. The site cannot show an amendment it has not yet worked in, so the issuing department is the cross-check.

    Working with an agent that can be wrong

    An agent that can run programs on my computer and drive my browser can do a great deal in an afternoon. It can also be wrong about a file it has not looked at, and it writes fluent explanations of things that did not happen. The rules I work under came out of incidents.

    The separation rule came first. The Thai library sits beside the Indian one on the same disk, and early on a Thai backup was written into the Indian backup folder. Nothing was lost, but since then a guard refuses any path under the Indian backups, and a checker audits every script for where it can reach. Building that checker produced two of the stranger moments of the month:

    • io.open(path, "w", newline=...) empties the file before it raises on a bad newline argument. The checker truncated itself to zero bytes that way. Everything now writes to a temporary file and os.replaces it.
    • A Windows path such as D:\...\Thai_Backup is, to a Linux program, an ordinary file name. Run from the agent’s side, a backup created a folder whose name was the whole Windows path, inside the library. It looked like a successful backup.

    The second rule is that every claim has to be shown. If the agent says a backup exists, it shows the listing. If it asks me to run a file, it first opens that file and quotes the line that does the work. That rule came after a session with five errors of this kind, one of which was a recommendation to run a batch file that would have thrown away three days of work.

    The third is a backup before anything that rewrites a file. Once, a batch file suggested in passing rewrote a file another script had written its OCR results into, and hours of machine time went with it. Now a copy comes first, and both checksums are shown. On 1 October that rule ran on something small: one translation cache file carried 1,443 NUL bytes left over from an interrupted run on 29 September. Nothing was lost, since the work had been redone, but the copy was taken, the bad line removed and all 776 cache files scanned before the index was rebuilt.

    The agent works within limits I set. It uses the sites’ public pages and endpoints only, respects robots.txt, does not solve CAPTCHAs, enter passwords or handle login tokens, and anything I have to do myself comes as numbered steps from the first click. When it saves a file from a page, the page builds the file and a click on a link saves it to my Downloads folder.

    PDFs that show one thing and say another

    Not everything comes through the endpoint. Ministerial regulations, schedules and forms come as PDFs, and a PDF can look perfect on screen while its text layer says something else. The page is drawn from the glyph outlines in the embedded font; text extraction goes through a separate mapping from character codes to Unicode (the ToUnicode map, or the font’s encoding and glyph names when there is no map). If that mapping is wrong, the screen is right and the text is junk.

    Three faults turned up.

    Broken glyph maps. The outlines were intact; only the map was broken. So every glyph outline was hashed, hash-to-character was learned from pages whose maps are sound, and the junk glyphs were looked up by shape. On the first 29 junk pages that gave 27,277 glyphs and 88 distinct shapes, all decoded. One bug worth remembering: the font cache was keyed by PDF object id, and object ids repeat across files.

    Mac Thai. Seven files decoded at 0% through the glyph table. All used one font pair, and the glyph names inside were Mac Roman names standing at the positions of Apple’s old Mac OS Thai encoding. The text was Thai written in Mac Thai and read back as Mac Roman. The repair is a table:

    # simplified; Python has no mac_thai codec
    MAC_EXTRA = {0x83: "\u0E48", 0x88: "\u0E48", 0x89: "\u0E49", 0x8C: "\u0E4C",
                 0x92: "\u0E31", 0x93: "\u0E47", 0x94: "\u0E34", 0x95: "\u0E35",
                 0x97: "\u0E37", 0x8D: "\u201C", 0x8E: "\u201D"}
    
    def macthai_decode(s):
        out = []
        for ch in s:
            try:
                b = ch.encode("mac_roman")[0]
            except UnicodeEncodeError:
                out.append("\uFFFD"); continue
            if b < 0x80:
                out.append(ch)
            elif 0xA1 <= b <= 0xFB:            # Thai letters as in TIS-620; Apple's dashes and
                                               # symbols in this range differ and come out unknown
                out.append(bytes([b]).decode("cp874", errors="replace"))
            elif b in MAC_EXTRA:               # Apple's extra bytes, read from the pages
                out.append(MAC_EXTRA[b])
            else:
                out.append("\uFFFD")           # counted as unknown, never guessed
        return "".join(out)

    The first trial dropped every ส. Mac Roman 0xCA is a no-break space; in Mac Thai, 0xCA is ส, and the first trial read it as a space. A wrong decode can also come out looking like Thai, so a decoded page is accepted only if Thai spelling holds: a vowel or tone mark must follow a consonant, the leading vowels must precede one, and the violation rate must be under 1%.

    Sara aa written as sara am. Ten PDFs, 30 pages, wrote every า as ำ, and every real ำ with a space in front of it: กำร for การ, ก ำหนด for กำหนด. The page test called them Thai, because they are Thai letters. The repair is exact:

    # simplified
    import re
    MARK = "\uE000"
    def fix_sara_aa(t):
        t = re.sub(r" ([\u0E48-\u0E4B]?)\u0E33", lambda m: m.group(1) + MARK, t)  # " ำ" is the real ำ
        return t.replace("\u0E33", "\u0E32").replace(MARK, "\u0E33")             # every other ำ is า

    Detection is by impossible spellings, กำร, ตำม, จำก and a few more, appearing at least twice with none of the correct forms on the page. On the PDF folder it selected exactly those 30 pages. One of the ten files was the Land Code regulation on registration fees for transfers and mortgages.

    Then a check against the official source became possible. Seventy-three regulations under the main Acts came back as official text through the endpoint, with the same identifiers as PDFs already read. The measure is the share of each PDF page’s Thai letters found, in order, in the official text:

    method     pages   median
    macthai      24    0.984
    glyph        31    0.978
    pua          38    0.978
    layer       108    0.942
    ocr         160    0.717

    layer is a text layer taken as it is, pua a layer using the Unicode private-use area. Every page below 0.8 that was not one of the sara aa pages was a form or an annex: the official text holds the operative regulation only, and the PDF is the only source for forms and schedules. The 0.717 median for Tesseract on scanned Thai is why OCR text sits at T4. Thai numerals are the worst of it.

    Machine English I will not quote

    Accurate Thai I cannot read is of limited use to me. So every section has a machine English rendering, made locally by Google’s open Gemma model (gemma3:27b) through Ollama on an RTX 5090. The 26,978 sections were split into 27,198 pieces for translation, and the run log records about 36 hours of model time between the evening of 28 September and the afternoon of 30 September.

    All of it is T4. The checks were there to make it good enough to search with and to read beside the Thai.

    1. Refusal at translation time: an answer is refused if it is empty, mostly Thai, far too short or far too long for the Thai it came from.
    2. Mechanical checks on every piece after every run: numbers in the Thai missing from the English; a section number that differs; a suffix section (มาตรา ๓ ตรี) not rendered as “3 ter”; fewer numbered items than the Thai; runaway repetition; chatter such as “Here is the translation”. A failure goes back with the reason written into the retry prompt, at most twice; after that it is listed for reading.
    3. A sample sheet of 30 random pieces, Thai beside English, at the end of every report.
    4. A termbase adherence table: for each fixed legal term, how often the English used the agreed rendering, and the Thai contexts the term turned up in.

    The fourth caught the best mistake of the month. The termbase said อาศัย means “habitation”, as in a right of habitation. Only 24% of pieces followed it, and the commonest context was อาศัยอำนาจ, “by virtue of the power”. The word inside other words was being translated as habitation. Land Code section 96 bis came out as aliens obtaining land “through habitation based on a treaty”; the Thai says by virtue of a treaty. The entry was narrowed to สิทธิอาศัย, right of habitation, and the bad renderings fell from 202 to 6, each of the 6 a proper use.

    Flagged pieces fell from 83 on the first pass to 7 on the last. Claude read those 7 against the Thai: six are real omissions of a number or a cross-reference and are listed as known defects, and one is a typo in the source. That is a machine checking a machine, which is the reason none of it is ever quoted.

    One file, a fifth of a second

    The Indian library runs on parquet files and DuckDB, because a million judgments need it. This one is a single SQLite file with two FTS5 indexes.

    • Thai uses the trigram tokenizer (SQLite 3.34 or later). Thai is written without spaces between words, and trigram matching needs no word-splitting. A query term shorter than three code points cannot use the trigram index, so it falls back to LIKE. Thai vowels and tone marks are separate code points, so ที่ is three of them.
    • English uses Porter stemming with prefix matching, a small synonym list (sale/sell, land/immovable, wife/spouse, foreigner/alien), and the termbase: an English phrase that matches a termbase rendering also searches the Thai term, at half weight.

    SQLite could not write its database file on the folder as the agent’s environment mounts it; the first attempt failed with disk I/O error. So the index is built in memory and written out in one go:

    # simplified; serialize() needs Python 3.11+
    import os, sqlite3
    mem = sqlite3.connect(":memory:")
    mem.execute("CREATE VIRTUAL TABLE fts_th USING fts5(text_th, tokenize='trigram')")
    # ... load sections, agency texts, notes ...
    with open(tmp_path, "wb") as f:
        f.write(mem.serialize())
    os.replace(tmp_path, index_path)   # the old index survives until the new one is complete

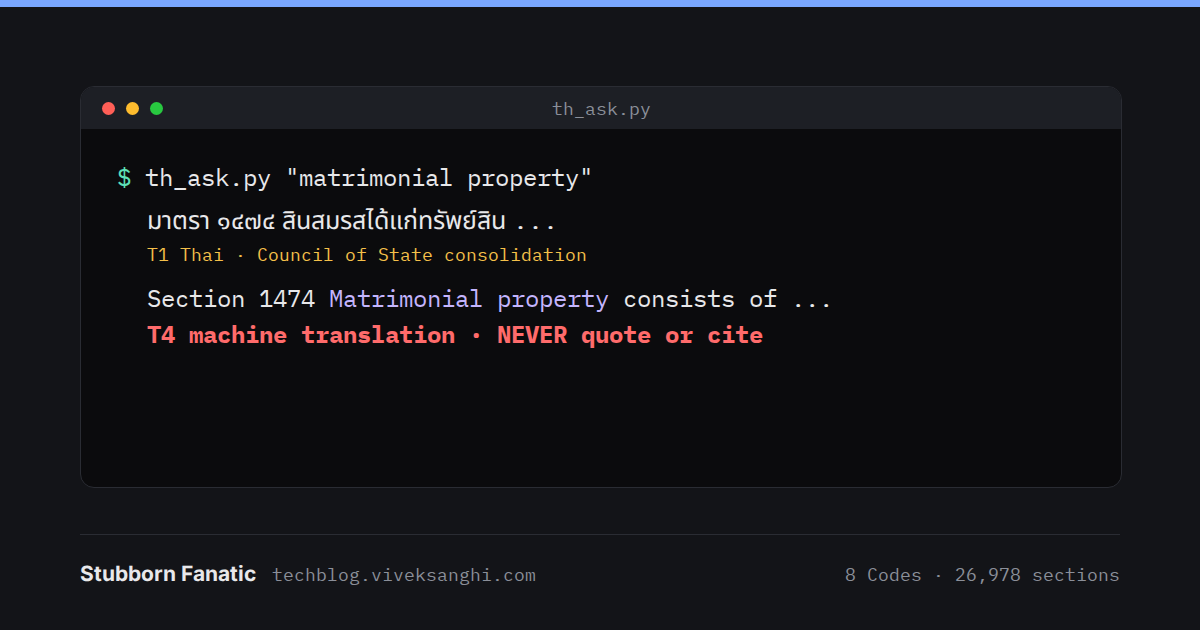
    A search looks like this. The square brackets mark the words that matched:

    python3 th_ask.py "matrimonial property"
    
    Civil and Commercial Code, section 1474
      TH  [T1 Thai, Council of State consolidation, in force from 2025-03-25]
          มาตรา ๑๔๗๔ สินสมรสได้แก่ทรัพย์สิน (๑) ที่คู่สมรสได้มาระหว่างสมรส ...
      EN  [T4 machine translation - NEVER quote or cite]
          Section 1474 [Matrimonial] [property] consists of [property] (1) which
          the spouses obtained during marriage. ...

    As of 1 October 2026: 26,978 sections, all with machine English; 1,218 third-party English pages; about 8,400 chunks of agency, tax, OCR, treaty and note text. The index is 146 MB, a full rebuild takes about 11 seconds, and a search returns in 0.1 to 0.2 seconds. I looked at moving it to the parquet-and-DuckDB layout of the Indian library and left it as it is. That layout exists for a 5.8 GB judgment index; an 11-second rebuild gains nothing from it.

    Case law, later

    Thai Supreme Court decisions are not in the library yet. That is a choice of order. In a civil law system a Supreme Court decision is not a precedent that binds; it carries persuasive weight and helps in reading the Code. The statute book had to come first. Case law is on the list for later, as a targeted set of decisions on property, family and succession rather than a bulk download.

    What I check before relying on it

    • The machine English. It is for finding and reading. Anything to be acted on needs an official English text where one exists, or a reading of the Thai by someone who reads it.
    • The consolidations. They trail behind amendments; the issuing department is the cross-check.
    • OCR text. It finds the page; then the page is read.
    • Forms and schedules. They exist only in the PDFs, and some of those PDFs are still unread.
    • The Bank of Thailand’s PDFs. 1,821 pages with junk text layers are measured and not solved. An improved glyph method can hash 98% of their glyphs, but more than half of those glyphs never appear on a clean page to learn from.

    What this is for

    I wanted to start any question of Thai law that touches my own affairs from the Thai text, with an honest label on every English word I lean on. The library does that now. A search gives me a Thai section, a T4 rendering to tell me what it says, and an official source to confirm it in.

    A note on what this is not

    I am an advocate enrolled in India. I am not a Thai lawyer, I do not practise Thai law, and as a foreign national I could not. Thai law allows only Thai nationals to register as lawyers (Lawyers Act B.E. 2528, section 35), and legal and litigation services are among the work Thai law reserves to Thai nationals, with narrow exceptions for arbitration. This library is a personal research tool for my own affairs. Nothing in this post is advice on Thai law. For any Thai-law matter, consult a lawyer licensed in Thailand.

    The texts in the library are public: Thai legislation, regulations, official notices and judgments, and translations of them made by Thai state agencies, are outside copyright under the Thai Copyright Act (section 7). Third-party English is held for private research only and is not reproduced here.

    Glossary

    B.E.: Buddhist Era. Thai dates count from it; B.E. = C.E. + 543, so B.E. 2569 is 2026.

    Council of State (ocs.go.th): the Thai government’s legal drafting office, which publishes consolidated texts of Thai laws.

    Consolidation: the text of a law with its amendments worked in. A convenience; the law itself is what was published in the Royal Gazette.

    Royal Gazette: the official gazette in which Thai laws are published and from which they take effect.

    มาตรา: section. bis, ter, quater: inserted sections numbered after an existing one.

    Termbase: a fixed list of Thai legal terms and their agreed English renderings, used to keep the machine translation consistent.

    FTS5: SQLite’s full-text search extension. Trigram tokenizer: indexes every run of three characters, so text without word boundaries can be searched without splitting it into words.

    ToUnicode map: the table inside a PDF that tells software which Unicode character each character code stands for. When it is wrong, a page looks right and extracts as nonsense.

    Mac Thai: Apple’s old 8-bit encoding for Thai, close to TIS-620 for the letters, with extra bytes for tone marks and vowels.

    OCR: optical character recognition. Tesseract is the open-source OCR engine used here.

    กฎหมายที่ผมอ่านไม่ออก

    ผมมีผลประโยชน์ทางกฎหมายอยู่ในประเทศไทย แต่ผมอ่านภาษาไทยไม่ออก

    สำหรับคนเป็นนักกฎหมาย นี่เป็นสถานการณ์ที่ลำบากใจ กฎหมายไทยประกาศใช้เป็นภาษาไทย และตัวบทภาษาไทยคือตัวกฎหมาย ฉบับภาษาอังกฤษใด ๆ เป็นเพียงการอ่านของใครคนหนึ่ง สำหรับประมวลกฎหมายที่ว่าด้วยทรัพย์สิน ครอบครัว และมรดก หน่วยงานยกร่างกฎหมายของรัฐบาลไทยเองไม่มีตัวบทภาษาอังกฤษเลย ผมตรวจสอบแล้ว และวิธีที่ผมตรวจสอบก็เป็นส่วนหนึ่งของบทความนี้

    ผมจึงสร้างห้องสมุดกฎหมายแห่งที่สองขึ้นในคอมพิวเตอร์ของตัวเอง แห่งแรกเป็นตัวบทและคำพิพากษาของอินเดีย ซึ่งเป็นอีกโครงการหนึ่ง แห่งนี้เก็บกฎหมายไทยเป็นภาษาไทย ภาษาอังกฤษทุกบรรทัดมีป้ายบอกว่าเชื่อถือได้แค่ไหน และค้นหาได้ในเสี้ยววินาที

    ผมสร้างมันร่วมกับ Claude โมเดล AI ของ Anthropic ซึ่งทำงานในฐานะเอเจนต์ คือสั่งรันโปรแกรมบนคอมพิวเตอร์ของผมและใช้เบราว์เซอร์ Chrome ของผมได้ ภายใต้กฎที่ผมกำหนด การตัดสินใจเป็นของผม สคริปต์และการสืบค้นส่วนใหญ่มาจากโมเดล และความผิดพลาดจำนวนไม่น้อยก็เช่นกัน งานเริ่มเมื่อวันที่ 4 กันยายน 2026 และส่วนใหญ่ทำในสัปดาห์สุดท้ายของเดือนกันยายน

    ขอกล่าวไว้ก่อนเรื่องอื่น ผมเป็นทนายความอินเดีย ไม่ใช่ทนายความไทย บทความนี้เล่าเรื่องการสร้างเครื่องมือค้นคว้า ไม่ใช่คำแนะนำเกี่ยวกับกฎหมายไทย รายละเอียดอยู่ในหมายเหตุท้ายบทความ

    ภาษาอังกฤษทุกคำต้องมีป้าย

    การตัดสินใจแรกคือกฎว่าด้วยภาษาอังกฤษ

    ประเทศไทยใช้ระบบซีวิลลอว์ ศาลไทยไม่ผูกพันตามคำพิพากษาก่อนหน้าอย่างเป็นทางการ รวมถึงคำพิพากษาศาลฎีกา แม้คำพิพากษาเหล่านั้นจะมีน้ำหนักก็ตาม ตัวบทกฎหมายจึงสำคัญกว่าคำพิพากษา และตัวบทเป็นภาษาไทย ถ้าผมจะพึ่งพาสิ่งเหล่านี้ ประโยคภาษาอังกฤษทุกประโยคต้องบอกได้ว่ามาจากไหน

    จึงแบ่งเป็นสี่ระดับ:

    T1  ตัวบทภาษาไทยที่เป็นทางการ หรือภาษาอังกฤษที่หน่วยงานเผยแพร่เป็นส่วนหนึ่งของตัวกฎหมาย
    T2  ภาษาอังกฤษที่หน่วยงานรัฐของไทยเผยแพร่ โดยระบุว่าไม่เป็นทางการ
    T3  ภาษาอังกฤษจากบุคคลภายนอก เช่น คำแปลเชิงพาณิชย์ เว็บไซต์สำนักงานกฎหมาย
    T4  ผลงานแปลด้วยเครื่องของเราเอง ใช้เพื่อค้นหาและอ่านเท่านั้น ห้ามยกอ้าง ห้ามอ้างอิง

    ไฟล์ข้อความทุกไฟล์มีบรรทัด tier: ในส่วนหัว และเครื่องมือค้นหาพิมพ์ระดับไว้ข้างผลลัพธ์ทุกรายการ ภาษาอังกฤษที่แปลด้วยเครื่องจะขึ้นป้าย T4 machine translation - NEVER quote or cite เป็นตัวพิมพ์ใหญ่ทุกครั้ง ป้ายนี้คือสิ่งที่กันไม่ให้ประโยคที่อ่านลื่นไหลกลายเป็นข้อความที่ถูกนำไปอ้างอิง

    ตามหาตัวบท

    สำนักงานคณะกรรมการกฤษฎีกาเผยแพร่ตัวบทกฎหมายไทยฉบับปรับปรุงอย่างเป็นทางการ ที่อยู่เดิม krisdika.go.th ไม่ได้ให้บริการแล้ว หน่วยงานย้ายไปที่ ocs.go.th

    หน้าค้นหาของเว็บไซต์ใหม่ทำงานบน endpoint แบบ form-encoded คือ POST /searchlaw/indexs/list_table_search มีสองเรื่องที่ขวางอยู่ก่อนจะได้รายการที่ครบถ้วน

    เรื่องแรกคือ TLS เซิร์ฟเวอร์ไม่ส่งใบรับรองระดับกลาง (intermediate certificate) มาด้วย เบราว์เซอร์ไปดึงใบรับรองที่ขาดมาเองได้ แต่ไลบรารี requests ของ Python ทำไม่ได้และล้มเหลว การตั้ง verify=False จะทำให้ข้อผิดพลาดหายไปด้วยการปิดการตรวจสอบ วิธีที่ใช้แทนคือ truststore ซึ่งส่งงานตรวจสอบไปให้ระบบสร้างสายการรับรองของ Windows เอง และ Windows หาใบรับรองระดับกลางที่ขาดได้ การตรวจสอบจึงยังคงเกิดขึ้น

    เรื่องที่สองคือตัวกรอง หน้าค้นหาของเว็บไซต์ส่งพารามิเตอร์ query[lawCategoryName] ด้วยค่า 1B,1C เมื่อส่งแบบนั้น ดัชนีซ่อนไป 7 รายการจาก 147 รายการ เมื่อส่งเป็นค่าว่าง ได้ครบทั้ง 147 รายการ ถ้าไม่นับทั้งสองแบบ ผมคงไม่รู้

    ผลที่ได้คือชื่อกฎหมายและไฟล์ PDF แต่ยังไม่ใช่ตัวบท ตัวบทอยู่หลังหน้าแสดงผลซึ่งเป็นแอป Angular แบบหน้าเดียว และ endpoint ห้าแห่งที่ลองเดาได้ผล 404 ทั้งหมด สิ่งที่ได้ผลคือเปิดหน้าแสดงผลในเบราว์เซอร์ แล้วอ่านดูว่าหน้าเว็บขอตัวบทจากเซิร์ฟเวอร์อย่างไร จากการรับส่งข้อมูลบนเครือข่ายและจาก JavaScript bundle ของมัน หน้าแสดงผลใช้ endpoint JSON สาธารณะ:

    POST https://searchlaw.ocs.go.th/ocs-api/public/doc/getLawDoc
    Content-Type: application/json
    
    { "reqHeader": { ...request id, channel, timestamp, service name... },
      "reqBody":   { "timelineId": "<id from the index>", "isTransEng": false,
                     "sectionIds": [], "sectionAndExplains": [] } }

    คำตอบที่ได้เป็นข้อมูลมีโครงสร้าง แต่ละมาตรามีเลขมาตรา ป้าย และเนื้อหา HTML พร้อมทุกฉบับของกฎหมายนั้น สำหรับประมวลกฎหมายแพ่งและพาณิชย์ ได้ 2,254 รายการ 605,706 ตัวอักษร ใช้บังคับตั้งแต่วันที่ 25 มีนาคม 2025 การดาวน์โหลดไฟล์บนเว็บไซต์เดียวกันใช้อีกเส้นทางหนึ่งที่ต้องมีโทเคนซึ่งหน้าแสดงผลถืออยู่ โทเคนนั้นไม่เคยถูกอ่านหรือนำไปใช้ซ้ำ ไฟล์ PDF ภาษาอังกฤษที่กล่าวถึงด้านล่างบันทึกผ่านปุ่มดาวน์โหลดของหน้าแสดงผลเอง เหมือนผู้อ่านทั่วไปบันทึกไฟล์

    ภาษาอังกฤษที่ไม่มีอยู่จริง

    คำขอเดียวกันนี้มีแฟล็ก isTransEng เมื่อตั้งเป็น true จะเป็นการขอภาษาอังกฤษ

    สำหรับประมวลกฎหมายไทยทั้งแปดฉบับ คำตอบคือ SUCCESS แต่มีศูนย์มาตรา ระบบรู้จักชื่อภาษาอังกฤษของประมวลกฎหมายเหล่านี้ แต่ไม่มีตัวบทภาษาอังกฤษเลย

    มีข้อยกเว้นอยู่หนึ่งกรณี ไทม์ไลน์ของประมวลกฎหมายแพ่งและพาณิชย์มี 73 ฉบับ และหนึ่งในนั้น คือตัวบทดั้งเดิมปี 1925 มีเครื่องหมายว่ามีคำแปล เป็นไฟล์ขนาด 242 KB ตลอดหนึ่งสัปดาห์ สมมติฐานในการทำงานคือไฟล์นี้เป็นคำแปลภาษาอังกฤษของประมวลฯ ฉบับปี 1925 เมื่อดาวน์โหลดไฟล์มาอ่าน หน้าปกบอกไว้อีกอย่าง มันคือพระราชบัญญัติแก้ไขเพิ่มเติมประมวลกฎหมายแพ่งและพาณิชย์ (ฉบับที่ 20) พ.ศ. 2557 เป็นพระราชบัญญัติแก้ไขเพิ่มเติมเพียงฉบับเดียว ที่ถูกจัดเก็บไว้กับฉบับดั้งเดิม

    บันทึกจึงได้รับการแก้ไข พร้อมวันที่แก้ และการอ่านเดิมยังคงถูกเก็บไว้ รายการในไทม์ไลน์บอกได้เพียงว่ามีไฟล์อยู่ ตัวไฟล์เองเท่านั้นที่บอกว่ามันคืออะไร

    สำนักงานคณะกรรมการกฤษฎีกามีภาษาอังกฤษสำหรับกฎหมายฉบับอื่น และตอนนี้ PDF เหล่านั้น 70 ไฟล์ ครอบคลุมกฎหมาย 57 ฉบับ อยู่ในห้องสมุดแล้ว จัดอยู่ในระดับ T2 และระบุไว้ในตัวเองว่าภาษาไทยเป็นฉบับที่มีผลบังคับแต่ผู้เดียว หลายไฟล์กลายเป็นพระราชบัญญัติแก้ไขเพิ่มเติม ไม่ใช่ตัวพระราชบัญญัติหลัก ซึ่งเป็นอีกเหตุผลหนึ่งที่ห้องสมุดนี้อ่านตัวบทฉบับปรับปรุงภาษาไทยก่อนเสมอ

    มาตรา 2 ที่ปรากฏ 36 ครั้ง

    เมื่อ endpoint ใช้งานได้ ประมวลกฎหมายทั้งแปดฉบับก็ถูกดึงลงมาเป็นข้อความมีโครงสร้าง ได้ 5,526 รายการ ในจำนวนนี้เป็นบทบัญญัติที่มีเลขกำกับ 4,453 รายการ จากนั้นการนับก็เริ่มขึ้น และบั๊กอยู่ในการนับนั่นเอง

    มาตรา 2 ปรากฏ 36 ครั้งในไฟล์ประมวลกฎหมายแพ่งและพาณิชย์ ไฟล์ของประมวลกฎหมายแต่ละฉบับมีพระราชบัญญัติที่แก้ไขประมวลฯ นั้นต่อท้ายไว้ และพระราชบัญญัติแต่ละฉบับก็นับมาตราของตัวเองเริ่มจาก 1 ถ้าปล่อยไว้อย่างนั้น การค้นหามาตรา 2 จะพบ 36 รายการ และมีเพียงรายการเดียวที่ถูก ตอนนี้ทุกรายการมีแฟล็กระบุว่าเป็นของตัวประมวลฯ เองหรือไม่ นี่คือเหตุที่ 2,254 รายการในไฟล์ประมวลกฎหมายแพ่งและพาณิชย์ เหลือเป็นบทบัญญัติของประมวลฯ 1,850 มาตรา ส่วนที่เหลือคือหัวข้อและพระราชบัญญัติที่ต่อท้าย

    ตัวอย่างอื่น ๆ:

    • ประมวลกฎหมายที่ดินมีแปดรายการติดกันที่ป้ายเขียนว่ามาตรา 105 ทั้งหมด ความจริงคือมาตรา 105, 105 ทวิ, ตรี ไปจนถึงอัฏฐ ฟิลด์ป้ายตัดเลขมาตราให้สั้นลง จึงต้องแยกเลขมาตราจริงจากตัวข้อความ
    • เลขลำดับคำเดียวกันสะกดได้สองแบบ คือ อัฎฐ ใช้ ฎ ในประมวลกฎหมายวิธีพิจารณาความแพ่ง และ อัฏฐ ใช้ ฏ ในประมวลกฎหมายที่ดิน
    • เว็บไซต์ส่งคอมเมนต์ HTML ที่ถูก escape มา คือ &lt;!--[endif]--&gt; ซึ่งจะกลายเป็นคอมเมนต์ก็ต่อเมื่อ unescape แล้ว ตัวลบคอมเมนต์จึงมองไม่เห็น selftest ผ่านเพราะ fixture ใช้คอมเมนต์จริง มันถูกเขียนจากวิธีแก้ ไม่ใช่จากข้อมูล

    เมื่อแก้ทั้งหมดนี้แล้ว ไม่มีเลขมาตราใดในประมวลกฎหมายทั้งแปดฉบับที่ซ้ำกันอีก

    เมื่อกฎหมายที่ถูกยกเลิกแล้วยังเป็น “ฉบับปัจจุบัน”

    แต่ละฉบับในไทม์ไลน์ของกฎหมายมี stateId กำกับ 01 ดูเหมือนแปลว่า “มีผลใช้บังคับ” และ 00 ดูเหมือนแปลว่า “ถูกแทนที่แล้ว”

    ในแถวดัชนี 652 แถวที่ชื่อมีคำว่า (ยกเลิก) มีถึง 638 แถวที่อยู่ในสถานะ 01 ฉบับสุดท้ายของกฎหมายที่ถูกยกเลิกแล้ว ยังคงเป็นฉบับปัจจุบันของกฎหมายนั้น การยกเลิกจึงอ่านจากเครื่องหมายในชื่อ ไม่ใช่จากสถานะ

    การทดสอบเมื่อวันที่ 24 กันยายน พบสถานะที่สาม คือ 02 ประกาศแล้วแต่ยังไม่มีผลใช้บังคับ พร้อมประเภทฉบับที่ห้า คือฉบับปรับปรุงล่วงหน้าที่แสดงว่ากฎหมายจะเป็นอย่างไรเมื่อการแก้ไขที่รออยู่มีผล วันที่ 30 กันยายน เรื่องนี้ทำให้เจอกับดัก พระราชกฤษฎีกาว่าด้วยภาษีมูลค่าเพิ่มฉบับหนึ่งแสดงฉบับปรับปรุงล่วงหน้าที่มีผลตั้งแต่วันที่ 1 ตุลาคม 2026 และไม่ได้รวมพระราชกฤษฎีกาแก้ไขอีกฉบับที่ลงวันที่เดียวกัน ซึ่งคงอัตราที่ลดลงไว้อีกหนึ่งปี ถ้าอ่านฉบับล่วงหน้านั้นเพียงลำพัง จะได้อัตราที่ผิด ตอนนี้ห้องสมุดเก็บพระราชกฤษฎีกาแก้ไขฉบับนั้นแยกไว้ และติดธงเตือนฉบับล่วงหน้าใดก็ตามที่เหมือนฉบับปัจจุบัน

    ในวันเดียวกัน ห้องสมุดทั้งหมดได้รับการตรวจเทียบกับสำนักงานคณะกรรมการกฤษฎีกา 837 รายการในไทม์ไลน์ของกฎหมายแม่บทที่เก็บไว้ และกฎหมาย 773 ฉบับไม่มีฉบับใดเปลี่ยนแปลงนับจากวันที่ดึงมา แต่ตัวบทฉบับปรับปรุงเองอาจตามหลังการแก้ไขกฎหมาย ฉบับปรับปรุงล่าสุดของประมวลรัษฎากรบนเว็บไซต์ลงวันที่ 9 พฤศจิกายน 2021 เว็บไซต์ไม่สามารถแสดงการแก้ไขที่ยังไม่ได้นำมารวม หน่วยงานที่ออกกฎหมายจึงเป็นแหล่งตรวจสอบซ้ำ

    ทำงานกับเอเจนต์ที่ผิดพลาดได้

    เอเจนต์ที่รันโปรแกรมบนคอมพิวเตอร์ของผมและควบคุมเบราว์เซอร์ของผมได้ ทำงานได้มากในบ่ายวันเดียว แต่มันก็ผิดได้เกี่ยวกับไฟล์ที่มันไม่ได้เปิดดู และมันเขียนคำอธิบายที่อ่านลื่นไหลถึงสิ่งที่ไม่ได้เกิดขึ้นจริง กฎที่ผมใช้ทำงานล้วนเกิดจากเหตุการณ์จริง

    กฎเรื่องการแยกส่วนมาก่อน ห้องสมุดไทยอยู่ข้างห้องสมุดอินเดียบนดิสก์เดียวกัน และในช่วงแรก ข้อมูลสำรองของฝั่งไทยถูกเขียนลงในโฟลเดอร์สำรองของฝั่งอินเดีย ไม่มีอะไรสูญหาย แต่นับจากนั้น มีตัวป้องกันที่ปฏิเสธทุกเส้นทางที่อยู่ใต้โฟลเดอร์สำรองของอินเดีย และมีตัวตรวจที่ตรวจทุกสคริปต์ว่าเข้าถึงที่ใดได้บ้าง การสร้างตัวตรวจนี้ทำให้เกิดเหตุการณ์แปลก ๆ สองครั้งในเดือนนั้น:

    • io.open(path, "w", newline=...) ล้างไฟล์ก่อนที่จะแจ้งข้อผิดพลาดเมื่ออาร์กิวเมนต์ newline ไม่ถูกต้อง ตัวตรวจลบเนื้อหาตัวเองจนเหลือศูนย์ไบต์ด้วยวิธีนี้ ตอนนี้ทุกอย่างเขียนลงไฟล์ชั่วคราวก่อน แล้วจึงใช้ os.replace สลับเข้าที่
    • เส้นทางแบบ Windows อย่าง D:\...\Thai_Backup สำหรับโปรแกรมบน Linux เป็นเพียงชื่อไฟล์ธรรมดา เมื่อสั่งจากฝั่งเอเจนต์ การสำรองข้อมูลจึงสร้างโฟลเดอร์ที่ชื่อเป็นเส้นทาง Windows ทั้งเส้นขึ้นมาในห้องสมุด ดูเผิน ๆ เหมือนการสำรองข้อมูลสำเร็จ

    กฎข้อที่สองคือทุกคำกล่าวอ้างต้องแสดงหลักฐาน ถ้าเอเจนต์บอกว่ามีไฟล์สำรองอยู่ มันต้องแสดงรายการไฟล์ ถ้ามันขอให้ผมรันไฟล์ใด มันต้องเปิดไฟล์นั้นก่อนและยกบรรทัดที่ทำงานจริงมาให้ดู กฎนี้เกิดหลังเซสชันหนึ่งที่มีข้อผิดพลาดแบบนี้ห้าครั้ง หนึ่งในนั้นคือคำแนะนำให้รันไฟล์ batch ที่จะทิ้งงานสามวันไป

    กฎข้อที่สามคือต้องสำรองข้อมูลก่อนทำอะไรก็ตามที่เขียนทับไฟล์ ครั้งหนึ่ง ไฟล์ batch ที่ถูกแนะนำมาแบบผ่าน ๆ ได้เขียนทับไฟล์ที่อีกสคริปต์หนึ่งบันทึกผล OCR ไว้ และเวลาประมวลผลของเครื่องหลายชั่วโมงก็หายไปด้วย ตอนนี้ต้องทำสำเนาก่อนเสมอ และต้องแสดงค่า checksum ทั้งสองค่า เมื่อวันที่ 1 ตุลาคม กฎนี้ถูกใช้กับเรื่องเล็ก ๆ ไฟล์แคชคำแปลไฟล์หนึ่งมีไบต์ NUL 1,443 ไบต์ที่หลงเหลือจากการทำงานที่หยุดกลางคันเมื่อวันที่ 29 กันยายน ไม่มีอะไรสูญหาย เพราะงานส่วนนั้นถูกทำใหม่แล้ว แต่ก็ทำสำเนาก่อน ลบบรรทัดที่เสีย และสแกนไฟล์แคชทั้ง 776 ไฟล์ก่อนสร้างดัชนีใหม่

    เอเจนต์ทำงานภายในขอบเขตที่ผมกำหนด มันใช้เฉพาะหน้าเว็บและ endpoint สาธารณะของเว็บไซต์ เคารพ robots.txt ไม่แก้ CAPTCHA ไม่กรอกรหัสผ่าน ไม่จัดการโทเคนสำหรับล็อกอิน และงานใดที่ผมต้องทำเอง จะมาเป็นขั้นตอนมีเลขกำกับตั้งแต่การคลิกครั้งแรก เมื่อมันบันทึกไฟล์จากหน้าเว็บ หน้าเว็บจะสร้างไฟล์ขึ้น แล้วการคลิกลิงก์จะบันทึกไฟล์ลงในโฟลเดอร์ Downloads ของผม

    PDF ที่แสดงอย่างหนึ่งแต่บอกอีกอย่างหนึ่ง

    ไม่ใช่ทุกอย่างที่มาทาง endpoint กฎกระทรวง บัญชีท้าย และแบบฟอร์ม มาในรูป PDF และ PDF อาจดูสมบูรณ์บนหน้าจอ ขณะที่ชั้นข้อความของมันบอกอีกอย่างหนึ่ง หน้ากระดาษวาดจากโครงร่าง glyph ในฟอนต์ที่ฝังไว้ ส่วนการดึงข้อความผ่านการจับคู่อีกชุดหนึ่งจากรหัสอักขระไปเป็น Unicode (ตาราง ToUnicode หรือ encoding และชื่อ glyph ของฟอนต์เมื่อไม่มีตาราง) ถ้าการจับคู่นั้นผิด หน้าจอจะถูก แต่ข้อความจะเป็นขยะ

    พบข้อผิดพลาดสามแบบ

    ตาราง glyph เสีย โครงร่างยังสมบูรณ์ มีแต่ตารางที่เสีย จึงแฮชโครงร่างของทุก glyph เรียนรู้การจับคู่แฮชกับตัวอักษรจากหน้าที่ตารางถูกต้อง แล้วค้นหา glyph ที่เสียด้วยรูปร่าง ใน 29 หน้าแรกที่เสีย ได้ 27,277 glyph จากรูปร่างที่ไม่ซ้ำกัน 88 รูป ถอดได้ทั้งหมด บั๊กหนึ่งที่ควรจำไว้ แคชฟอนต์ใช้ object id ของ PDF เป็นคีย์ และ object id ซ้ำกันข้ามไฟล์ได้

    Mac Thai เจ็ดไฟล์ถอดได้ 0% ผ่านตาราง glyph ทุกไฟล์ใช้ฟอนต์คู่เดียวกัน และชื่อ glyph ข้างในเป็นชื่อแบบ Mac Roman ที่วางอยู่ตามตำแหน่งของรหัส Mac OS Thai เก่าของ Apple ข้อความเป็นภาษาไทยที่เขียนด้วย Mac Thai แต่ถูกอ่านกลับเป็น Mac Roman วิธีซ่อมคือตาราง:

    # simplified; Python has no mac_thai codec
    MAC_EXTRA = {0x83: "\u0E48", 0x88: "\u0E48", 0x89: "\u0E49", 0x8C: "\u0E4C",
                 0x92: "\u0E31", 0x93: "\u0E47", 0x94: "\u0E34", 0x95: "\u0E35",
                 0x97: "\u0E37", 0x8D: "\u201C", 0x8E: "\u201D"}
    
    def macthai_decode(s):
        out = []
        for ch in s:
            try:
                b = ch.encode("mac_roman")[0]
            except UnicodeEncodeError:
                out.append("\uFFFD"); continue
            if b < 0x80:
                out.append(ch)
            elif 0xA1 <= b <= 0xFB:            # Thai letters as in TIS-620; Apple's dashes and
                                               # symbols in this range differ and come out unknown
                out.append(bytes([b]).decode("cp874", errors="replace"))
            elif b in MAC_EXTRA:               # Apple's extra bytes, read from the pages
                out.append(MAC_EXTRA[b])
            else:
                out.append("\uFFFD")           # counted as unknown, never guessed
        return "".join(out)

    ความพยายามครั้งแรกทำ ส หายไปทุกตัว ไบต์ 0xCA ใน Mac Roman คือช่องว่างไม่ตัดบรรทัด แต่ใน Mac Thai 0xCA คือ ส และครั้งแรกอ่านมันเป็นช่องว่าง การถอดรหัสที่ผิดก็อาจออกมาดูเหมือนภาษาไทยได้ หน้าที่ถอดแล้วจึงยอมรับเฉพาะเมื่อการสะกดแบบไทยถูกต้อง คือสระหรือวรรณยุกต์ต้องตามหลังพยัญชนะ สระหน้าต้องนำหน้าพยัญชนะ และอัตราการผิดต้องต่ำกว่า 1%

    สระอา ที่เขียนเป็นสระอำ PDF สิบไฟล์ 30 หน้า เขียน า ทุกตัวเป็น ำ และ ำ ตัวจริงทุกตัวมีช่องว่างนำหน้า เช่น กำร แทน การ และ ก ำหนด แทน กำหนด การตรวจหน้ากระดาษบอกว่าเป็นภาษาไทย เพราะเป็นตัวอักษรไทยจริง วิธีซ่อมแม่นยำ:

    # simplified
    import re
    MARK = "\uE000"
    def fix_sara_aa(t):
        t = re.sub(r" ([\u0E48-\u0E4B]?)\u0E33", lambda m: m.group(1) + MARK, t)  # " ำ" is the real ำ
        return t.replace("\u0E33", "\u0E32").replace(MARK, "\u0E33")             # every other ำ is า

    การตรวจจับใช้การสะกดที่ภาษาไทยไม่มี เช่น กำร ตำม จำก และอีกเล็กน้อย ที่ปรากฏอย่างน้อยสองครั้ง โดยไม่มีรูปที่ถูกต้องเลยในหน้านั้น ในโฟลเดอร์ PDF วิธีนี้เลือกได้ตรง 30 หน้านั้นพอดี หนึ่งในสิบไฟล์คือกฎกระทรวงตามประมวลกฎหมายที่ดินว่าด้วยค่าธรรมเนียมจดทะเบียนการโอนและการจำนอง

    จากนั้นก็สามารถตรวจเทียบกับแหล่งทางการได้ กฎกระทรวงและพระราชกฤษฎีกา 73 ฉบับภายใต้พระราชบัญญัติหลักได้ตัวบททางการกลับมาผ่าน endpoint โดยมีรหัสเดียวกับ PDF ที่อ่านไปแล้ว ตัววัดคือสัดส่วนของตัวอักษรไทยในแต่ละหน้า PDF ที่พบเรียงตามลำดับในตัวบททางการ:

    method     pages   median
    macthai      24    0.984
    glyph        31    0.978
    pua          38    0.978
    layer       108    0.942
    ocr         160    0.717

    layer คือชั้นข้อความที่ใช้ตามที่เป็น pua คือชั้นข้อความที่ใช้พื้นที่ private-use ของ Unicode ทุกหน้าที่ได้ต่ำกว่า 0.8 ซึ่งไม่ใช่หน้าที่มีปัญหาสระอา เป็นแบบฟอร์มหรือภาคผนวก ตัวบททางการมีเฉพาะบทบัญญัติที่ใช้บังคับ และ PDF เป็นแหล่งเดียวของแบบฟอร์มและบัญชีท้าย ค่ามัธยฐาน 0.717 ของ Tesseract กับภาษาไทยที่สแกนมา คือเหตุผลที่ข้อความจาก OCR อยู่ในระดับ T4 ตัวเลขไทยแย่ที่สุด

    ภาษาอังกฤษจากเครื่องที่ผมจะไม่ยกอ้าง

    ตัวบทไทยที่ถูกต้องแต่ผมอ่านไม่ออกมีประโยชน์กับผมไม่มากนัก ทุกมาตราจึงมีคำแปลภาษาอังกฤษด้วยเครื่อง ทำบนเครื่องของผมเองด้วยโมเดลเปิด Gemma ของ Google (gemma3:27b) ผ่าน Ollama บนการ์ดจอ RTX 5090 มาตรา 26,978 มาตราถูกแบ่งเป็น 27,198 ชิ้นเพื่อแปล และบันทึกการทำงานแสดงเวลาประมวลผลของโมเดลราว 36 ชั่วโมง ระหว่างค่ำวันที่ 28 กันยายน ถึงบ่ายวันที่ 30 กันยายน

    ทั้งหมดอยู่ในระดับ T4 การตรวจสอบมีไว้ให้มันดีพอสำหรับใช้ค้นหาและอ่านเคียงข้างภาษาไทย

    1. ปฏิเสธตั้งแต่ตอนแปล: คำตอบจะถูกปฏิเสธถ้าว่างเปล่า เป็นภาษาไทยเสียส่วนใหญ่ หรือสั้นหรือยาวเกินไปมากเมื่อเทียบกับภาษาไทยต้นทาง
    2. การตรวจด้วยโปรแกรมกับทุกชิ้นหลังการแปลทุกรอบ: ตัวเลขในภาษาไทยที่หายไปจากภาษาอังกฤษ เลขมาตราที่ไม่ตรงกัน มาตราที่มีคำต่อท้าย (มาตรา ๓ ตรี) ที่ไม่ได้แปลเป็น “3 ter” จำนวนรายการที่น้อยกว่าภาษาไทย ข้อความวนซ้ำ และคำพูดเกินเลยอย่าง “Here is the translation” ชิ้นที่ไม่ผ่านถูกส่งกลับไปพร้อมเหตุผลที่เขียนไว้ในคำสั่งแปลใหม่ ไม่เกินสองครั้ง หลังจากนั้นจะถูกจดไว้ให้อ่านตรวจ
    3. แผ่นตัวอย่าง 30 ชิ้นสุ่ม ภาษาไทยเคียงภาษาอังกฤษ ท้ายรายงานทุกฉบับ
    4. ตารางการใช้ศัพท์: สำหรับศัพท์กฎหมายแต่ละคำที่กำหนดไว้ ภาษาอังกฤษใช้คำแปลที่ตกลงไว้บ่อยแค่ไหน และศัพท์นั้นปรากฏในบริบทภาษาไทยแบบใด

    ข้อที่สี่จับความผิดพลาดที่ดีที่สุดของเดือนได้ รายการศัพท์กำหนดว่า อาศัย แปลว่า “habitation” อย่างในคำว่าสิทธิอาศัย แต่มีเพียง 24% ของชิ้นงานที่ทำตาม และบริบทที่พบบ่อยที่สุดคือ อาศัยอำนาจ ซึ่งแปลว่า “by virtue of the power” คำนี้เมื่ออยู่ในคำอื่นถูกแปลเป็น habitation มาตรา 96 ทวิ แห่งประมวลกฎหมายที่ดินออกมาเป็นคนต่างด้าวได้ที่ดิน “through habitation based on a treaty” ขณะที่ภาษาไทยหมายถึงโดยอาศัยบทสนธิสัญญา ศัพท์จึงถูกจำกัดให้แคบลงเป็น สิทธิอาศัย = right of habitation และคำแปลที่ผิดลดลงจาก 202 เหลือ 6 ซึ่งทั้ง 6 เป็นการใช้ที่ถูกต้อง

    ชิ้นที่ถูกติดธงลดลงจาก 83 ในรอบแรก เหลือ 7 ในรอบสุดท้าย Claude อ่านทั้ง 7 ชิ้นเทียบกับภาษาไทย หกชิ้นเป็นการตกหล่นของตัวเลขหรือการอ้างอิงมาตราจริง และถูกบันทึกไว้เป็นข้อบกพร่องที่ทราบแล้ว อีกหนึ่งชิ้นเป็นการพิมพ์ผิดในต้นฉบับ นี่คือเครื่องตรวจเครื่อง ซึ่งเป็นเหตุผลที่ไม่มีส่วนใดของมันถูกยกอ้างเลย

    ไฟล์เดียว เสี้ยววินาที

    ห้องสมุดฝั่งอินเดียใช้ไฟล์ parquet กับ DuckDB เพราะคำพิพากษาหนึ่งล้านฉบับต้องการเช่นนั้น แห่งนี้เป็นไฟล์ SQLite ไฟล์เดียวที่มีดัชนี FTS5 สองชุด

    • ภาษาไทยใช้ tokenizer แบบ trigram (SQLite 3.34 ขึ้นไป) ภาษาไทยเขียนโดยไม่เว้นวรรคระหว่างคำ และการจับคู่แบบ trigram ไม่ต้องตัดคำ คำค้นที่สั้นกว่าสาม code point ใช้ดัชนี trigram ไม่ได้ จึงถอยไปใช้ LIKE สระและวรรณยุกต์ไทยเป็น code point แยกกัน ดังนั้น ที่ จึงมีสาม code point
    • ภาษาอังกฤษใช้ Porter stemming กับการจับคู่คำนำหน้า รายการคำพ้องสั้น ๆ (sale/sell, land/immovable, wife/spouse, foreigner/alien) และรายการศัพท์ วลีภาษาอังกฤษที่ตรงกับคำแปลในรายการศัพท์จะค้นหาศัพท์ภาษาไทยด้วย โดยให้น้ำหนักครึ่งหนึ่ง

    SQLite เขียนไฟล์ฐานข้อมูลลงในโฟลเดอร์ตามที่สภาพแวดล้อมของเอเจนต์ mount ไว้ไม่ได้ ความพยายามครั้งแรกล้มเหลวด้วย disk I/O error ดัชนีจึงถูกสร้างในหน่วยความจำ แล้วเขียนออกมาครั้งเดียว:

    # simplified; serialize() needs Python 3.11+
    import os, sqlite3
    mem = sqlite3.connect(":memory:")
    mem.execute("CREATE VIRTUAL TABLE fts_th USING fts5(text_th, tokenize='trigram')")
    # ... load sections, agency texts, notes ...
    with open(tmp_path, "wb") as f:
        f.write(mem.serialize())
    os.replace(tmp_path, index_path)   # the old index survives until the new one is complete

    การค้นหาหน้าตาเป็นแบบนี้ วงเล็บเหลี่ยมคือคำที่ค้นเจอ:

    python3 th_ask.py "matrimonial property"
    
    Civil and Commercial Code, section 1474
      TH  [T1 Thai, Council of State consolidation, in force from 2025-03-25]
          มาตรา ๑๔๗๔ สินสมรสได้แก่ทรัพย์สิน (๑) ที่คู่สมรสได้มาระหว่างสมรส ...
      EN  [T4 machine translation - NEVER quote or cite]
          Section 1474 [Matrimonial] [property] consists of [property] (1) which
          the spouses obtained during marriage. ...

    ณ วันที่ 1 ตุลาคม 2026: 26,978 มาตรา ทุกมาตรามีคำแปลภาษาอังกฤษด้วยเครื่อง หน้าภาษาอังกฤษจากบุคคลภายนอก 1,218 หน้า และข้อความจากหน่วยงาน ภาษี OCR สนธิสัญญา และบันทึก ราว 8,400 ส่วน ดัชนีมีขนาด 146 MB สร้างใหม่ทั้งหมดในราว 11 วินาที และการค้นหาใช้เวลา 0.1 ถึง 0.2 วินาที ผมพิจารณาจะย้ายไปใช้โครงสร้าง parquet และ DuckDB แบบห้องสมุดอินเดีย แล้วก็คงไว้อย่างเดิม โครงสร้างนั้นมีไว้สำหรับดัชนีคำพิพากษาขนาด 5.8 GB การสร้างใหม่ที่ใช้เวลา 11 วินาทีไม่ได้ประโยชน์อะไรจากมัน

    คำพิพากษา ไว้ทีหลัง

    คำพิพากษาศาลฎีกาของไทยยังไม่อยู่ในห้องสมุดนี้ นี่เป็นการเลือกลำดับงาน ในระบบซีวิลลอว์ คำพิพากษาศาลฎีกาไม่ใช่บรรทัดฐานที่มีผลผูกพัน แต่มีน้ำหนักในการโน้มน้าวและช่วยในการตีความประมวลกฎหมาย ตัวบทกฎหมายจึงต้องมาก่อน คำพิพากษาอยู่ในรายการงานภายหลัง โดยจะเลือกเฉพาะคำพิพากษาเรื่องทรัพย์สิน ครอบครัว และมรดก ไม่ใช่ดาวน์โหลดทั้งหมด

    สิ่งที่ผมตรวจสอบก่อนจะพึ่งพา

    • ภาษาอังกฤษจากเครื่อง ใช้เพื่อค้นหาและอ่าน สิ่งใดที่จะนำไปใช้ดำเนินการ ต้องมีตัวบทภาษาอังกฤษที่เป็นทางการถ้ามี หรือต้องมีผู้ที่อ่านภาษาไทยได้อ่านตัวบทภาษาไทย
    • ตัวบทฉบับปรับปรุง อาจตามหลังการแก้ไขกฎหมาย หน่วยงานที่ออกกฎหมายคือแหล่งตรวจสอบซ้ำ
    • ข้อความจาก OCR ใช้หาหน้าที่ต้องการ แล้วจึงอ่านหน้านั้น
    • แบบฟอร์มและบัญชีท้าย มีอยู่ใน PDF เท่านั้น และ PDF บางไฟล์ยังไม่ได้อ่าน
    • PDF ของธนาคารแห่งประเทศไทย มี 1,821 หน้าที่ชั้นข้อความเสีย วัดแล้วแต่ยังแก้ไม่ได้ วิธี glyph ที่ปรับปรุงแล้วแฮช glyph ได้ 98% แต่มากกว่าครึ่งของ glyph เหล่านั้นไม่เคยปรากฏในหน้าที่สมบูรณ์ให้เรียนรู้

    ทำไปเพื่ออะไร

    ผมต้องการเริ่มต้นคำถามทางกฎหมายไทยใดก็ตามที่เกี่ยวกับเรื่องของผมเองจากตัวบทภาษาไทย โดยภาษาอังกฤษทุกคำที่ผมพึ่งพามีป้ายบอกที่มาอย่างตรงไปตรงมา ตอนนี้ห้องสมุดทำได้แล้ว การค้นหาให้มาตราภาษาไทย คำแปลระดับ T4 ที่บอกว่ามาตรานั้นว่าอย่างไร และแหล่งทางการให้ไปตรวจยืนยัน

    หมายเหตุ: สิ่งที่บทความนี้ไม่ใช่

    ผมเป็นทนายความที่จดทะเบียนในอินเดีย ผมไม่ใช่ทนายความไทย ผมไม่ได้ประกอบวิชาชีพกฎหมายไทย และในฐานะคนต่างชาติ ผมก็ทำไม่ได้ กฎหมายไทยให้เฉพาะผู้มีสัญชาติไทยจดทะเบียนเป็นทนายความได้ (พระราชบัญญัติทนายความ พ.ศ. 2528 มาตรา 35) และงานให้บริการทางกฎหมายหรืออรรถคดีเป็นงานที่กฎหมายไทยสงวนไว้สำหรับคนไทย โดยมีข้อยกเว้นแคบ ๆ สำหรับงานอนุญาโตตุลาการ ห้องสมุดนี้เป็นเครื่องมือค้นคว้าส่วนตัวสำหรับเรื่องของผมเอง ไม่มีส่วนใดในบทความนี้เป็นคำแนะนำเกี่ยวกับกฎหมายไทย สำหรับเรื่องกฎหมายไทยใด ๆ โปรดปรึกษาทนายความที่ได้รับใบอนุญาตในประเทศไทย

    ตัวบทในห้องสมุดเป็นเอกสารสาธารณะ กฎหมาย ระเบียบ ประกาศ คำสั่ง และคำพิพากษาของไทย รวมทั้งคำแปลที่หน่วยงานรัฐของไทยจัดทำ ไม่ถือเป็นงานอันมีลิขสิทธิ์ตามพระราชบัญญัติลิขสิทธิ์ (มาตรา 7) ภาษาอังกฤษจากบุคคลภายนอกเก็บไว้เพื่อการค้นคว้าส่วนตัวเท่านั้น และไม่ได้นำมาเผยแพร่ในที่นี้

    อภิธานศัพท์

    พ.ศ.: พุทธศักราช ไทยนับปีตามนี้ พ.ศ. = ค.ศ. + 543 ดังนั้น พ.ศ. 2569 คือ ค.ศ. 2026

    สำนักงานคณะกรรมการกฤษฎีกา (ocs.go.th): หน่วยงานยกร่างกฎหมายของรัฐบาลไทย ผู้เผยแพร่ตัวบทกฎหมายไทยฉบับปรับปรุง

    ฉบับปรับปรุง (consolidation): ตัวบทกฎหมายที่รวมการแก้ไขเพิ่มเติมไว้แล้ว ใช้เพื่อความสะดวก ตัวกฎหมายจริงคือสิ่งที่ประกาศในราชกิจจานุเบกษา

    ราชกิจจานุเบกษา: หนังสือราชการที่ใช้ประกาศกฎหมายไทย กฎหมายเริ่มมีผลนับจากการประกาศนี้

    ทวิ ตรี จัตวา: มาตราที่แทรกเพิ่มต่อจากมาตราเดิม เทียบได้กับ bis, ter, quater

    รายการศัพท์ (termbase): รายการศัพท์กฎหมายไทยพร้อมคำแปลภาษาอังกฤษที่ตกลงกันไว้ ใช้ให้คำแปลด้วยเครื่องสม่ำเสมอ

    FTS5: ส่วนขยายการค้นหาข้อความเต็มของ SQLite Trigram tokenizer: สร้างดัชนีจากทุกช่วงสามตัวอักษร ทำให้ค้นหาข้อความที่ไม่มีการแบ่งคำได้โดยไม่ต้องตัดคำ

    ตาราง ToUnicode: ตารางใน PDF ที่บอกซอฟต์แวร์ว่ารหัสอักขระแต่ละตัวคือตัวอักษร Unicode ใด ถ้าตารางผิด หน้าจะดูถูกต้องแต่ดึงข้อความออกมาเป็นขยะ

    Mac Thai: รหัสอักขระภาษาไทยแบบ 8 บิตรุ่นเก่าของ Apple ตัวอักษรใกล้เคียง TIS-620 โดยมีไบต์เพิ่มสำหรับวรรณยุกต์และสระ

    OCR: ซอฟต์แวร์รู้จำตัวอักษร Tesseract คือเครื่องมือ OCR แบบโอเพนซอร์สที่ใช้ในงานนี้
  • The section that wasn’t there

    The section that wasn’t there

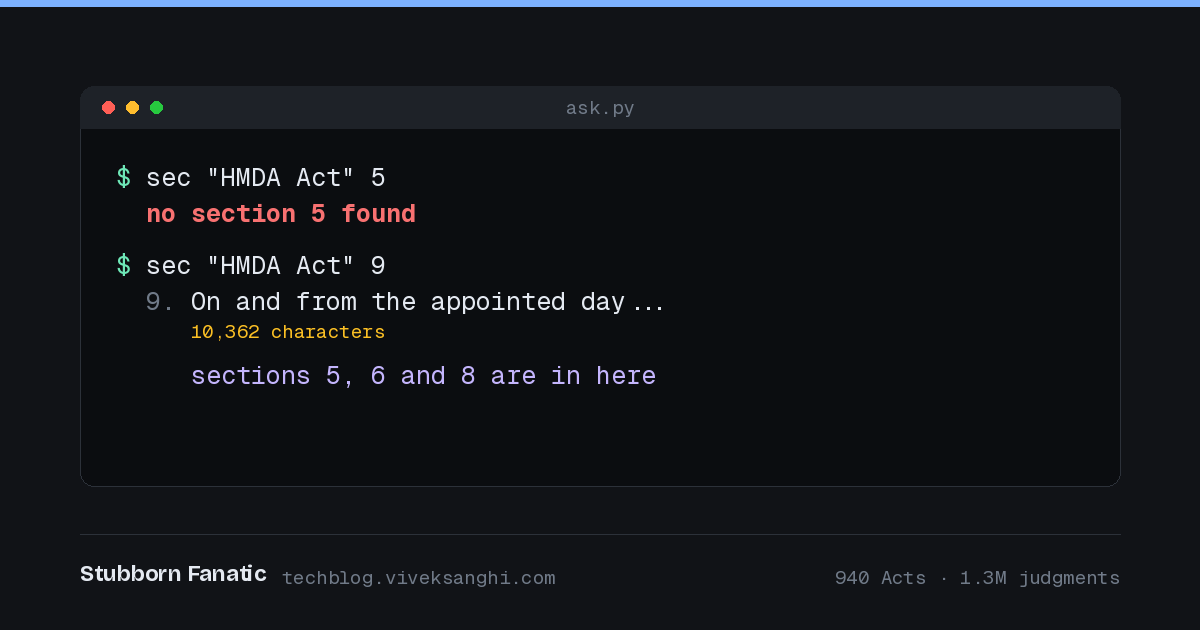
    I asked my own law database for section 5 of the Hyderabad Metropolitan Development Authority Act, 2008. It told me there was no such section.

    There is. It is on the printed page in front of me. The database had the text, all of it, and could not find it, because the text was filed under a different number.

    This is a post about building a searchable corpus of Indian statutes and case law on my own machine, and about the fact that the dangerous failure is never the database that says nothing. It is the one that answers with confidence and is wrong.

    I built it over several weeks with Claude. I made the decisions, ran everything on my own hardware, and checked the law myself; the scripts and most of the analysis came from the model. The mistakes are in here as well, because on a project of this shape the mistakes are the content. Nearly every genuine improvement came from something being printed to screen that looked wrong.

    Why hold law locally at all

    I am an advocate in Hyderabad. My practice is property, title due diligence, drafting. The work needs the text of statutes, rules, government orders and judgments, constantly, and mostly for a narrow set of jurisdictions: Central Acts, Telangana, and the Andhra Pradesh that Telangana inherited.

    The obvious answer is a subscription database. They work. But two things pushed me the other way.

    The first is cost and dependence. The second matters more: I cannot audit what I cannot see inside. When a subscription database returns nothing for a section, I have no way of knowing whether the section does not exist, or whether their ingestion mangled it the way mine mangled HMDA section 5. When my own corpus does that, I can go and look.

    There is also a speed argument that turns out to be real. Searching a million judgments on my own machine takes about a second.

    What the corpus is made of

    The whole thing lives at D:AiTools on a Windows workstation, a Ryzen 9950X3D with 64 GB of RAM. The pipeline is deliberately dull: scrape original sources, convert to markdown, write parquet, query with DuckDB. No database server, no index server, nothing to keep running. Files on a disk.

    An early decision shaped everything after it. There is a bulk dataset of Indian legislation on Hugging Face, and I downloaded it. Then I decided not to use it for statutes, and to scrape India Code and the Telangana Law Department fresh instead. Not because the dataset is bad, but because I wanted to know the provenance of every section I might cite, and to be able to go back to the page it came from. I kept the dataset to cross-check against, once.

    What the Act surface holds today, counted this morning:

    58,381 rows across eight parquet files
    
      India Code       828 Central Acts     35,390 sections
                       112 Telangana Acts    1,542 sections
      Telangana Law Dept   184 Acts
      Schedules            380 Acts          1,484 schedule rows
      Act-level PDFs       452 Acts
          196  Andhra Pradesh, pre-2014, applies in Telangana
          179  Telangana
           56  Andhra Pradesh, post-2014, residuary AP only
           18  Central
      Harvested G.O.s, circulars, orders   757 rows

    Separately there is an index of my own prior work: 18,932 documents out of my OneDrive, read-only, so a search can turn up the deed I drafted in 2019 alongside the section it relied on.

    That AP split is not decorative. Andhra Pradesh was bifurcated on 2 June 2014, and an AP Act from before that date still applies in Telangana while one from after it does not. Every result line says which, because an Act that does not apply is still an Act, and the distinction has to survive into whatever is filed.

    Counting is not checking

    Here is the mistake that reshaped how I check this corpus.

    The corpus held the HMDA Act with 58 sections, numbered up to 58. That looks complete. It is not. Sections 5, 6 and 8 were absent, and their text was inside the row filed as section 9, a row that opens with the repeal of a 1988 water-rates ordinance and runs to 10,362 characters, having swallowed several sections that come before it.

    The cause is visible on the printed page. HMDA prints its section headings as marginal notes, in a column beside the body text. Extract a text layer from that PDF and the headings interleave with the sentences, so 5. never begins a line, and a splitter looking for a number at the start of a line never sees one.

    So I stopped trusting counts and audited numbering continuity instead: for every Act holding eight or more numbered sections, is the run of numbers unbroken?

    When that ran, on 27 August 2026, it found 1,151 Acts with eight or more sections and 99 with a gap. Most gaps are honest: sections repealed, or omitted from the source. But in 38 of them the missing section’s heading was present inside another row. The text was in the corpus, filed under the wrong number.

    Re-running the same audit today gives 1,158 Acts and 86 gaps. The difference is the repair described below.

    The consequence is worth stating plainly. Full-text search reaches misfiled text without difficulty. It is a lookup by section number that fails, and it fails by reporting that a section does not exist when it does. That is the wrong direction to fail in.

    repair.py, and five ways it nearly filed the wrong text

    Recovering misfiled sections sounds simple: find the missing number used as a heading inside another row, cut from there to the next heading, file it under its own number.

    It is not simple, and the first version was wrong in five separate ways. All five were found by running it in a sandbox and reading the output before it touched anything.

    It missed the section it was written for. The heading pattern required text to continue on the same line. India Code prints 5. alone, with (1) There shall be... on the line below. HMDA section 5, the whole reason the script existed, did not match.

    Cuts ran to the end of the host row. A recovered section 8 swallowed section 9 and everything after it. Cuts now end at the next heading of any number.

    Footnotes were recovered as sections. 54. Section 43 substituted by Act No.11 of 1969 is a footnote. It looks exactly like a section heading.

    Page-group rows were used as hosts. Where an Act could not be split reliably it is stored as page groups, which contain the entire text, so every number appears in them. Recovering from those produces nonsense.

    The same number was recovered from six different rows of the Wealth-tax Act.

    The gate that did most of the work is a structural one: a row can only have swallowed sections that precede it. So a recovered number must be lower than its host’s number and within 40 of it. Without that gate, the Greater Hyderabad Municipal Corporation Act “recovered” section 19 out of a row filed as section 687, which is a schedule of cycle-rickshaw fees.

    Ungated, the pass proposed 34 Acts and 133 sections. Gated, it proposed 23 Acts and 49 sections, and the 23 rejected candidates each carry a stated reason.

    Today repairs_acts.parquet holds 49 recovered sections across 23 Acts, each labelled with the row it was cut from and marked medium confidence. It never edits another script’s file. The recovered rows join the same glob the reader already reads.

    A correction

    An earlier note of mine recorded that the GHMC Act had “37 of 53 gaps recoverable”. That was wrong, and it came from a crude heading search with none of the gates above.

    A properly gated pass recovers nothing from GHMC. Its numbering gaps are footnote markers and schedule item numbers, not missing sections. Today the audit still shows GHMC with 635 sections present and 52 numbers missing, and that is the correct answer: they were never sections.

    I am recording the wrong figure as well as the right one because a corpus you cannot correct in public is a corpus nobody should trust, including you.

    Heuristics that fail interestingly

    Three gates keep schedules and tables out of the recovery pass, and each was calibrated against real documents.

    Digit density. Statutory prose runs 3 to 4 per cent digits. Schedules run 24 per cent and up. The threshold sits at 18. This caught a recovered “section” of 247,454 characters that was the Telangana Panchayat Raj Act’s schedule of village names.

    Line length. Text laid out as a table puts each field on its own line. Village schedules average 9 characters per line; statutory prose averages 75.

    That second gate was first set at 28 characters, and it rejected HMDA sections 5 and 8. India Code wraps its prose at about 27, and a section that is a list of committee members has short lines. A threshold tuned on the wrong sample rejected precisely the sections the whole exercise existed to recover. Moved to 15, the pass went from 44 sections to 49, the five additions being HMDA sections 5 and 8, Telangana Municipalities section 32, and two sections of the Telangana State Private Universities Act.

    Capture ratio. Any split that captures under 92 per cent of a document’s text is rejected in favour of page chunks. This exists because of a specific failure: an Act splitter applied to a Government Order treats the numbered list of earlier G.O.s it cites as the sections. G.O.Ms.No.59 came out as a single “section 4” holding 47 per cent of the document, with the abstract and the operative order silently gone. Instruments that are not Acts, Rules or Regulations are no longer split at all.

    Fifty gigabytes of judgments, and what they do not carry

    Judgments come from the open-india-law dataset: 63 parquet files, 53.7 GB. I hold all of them.

    The indexed corpus covers the courts that matter to my practice:

      telangana        1,005,147 judgments
      andhra-pradesh     261,778
      supreme-court       37,014

    Now the part that decides how you use this data. Metadata completeness, measured this morning:

      court            judgments    no citation   no judges
      telangana        1,005,147        100.0%       81.9%
      andhra-pradesh     261,778        100.0%       88.3%
      supreme-court       37,014          0.0%        0.0%

    Every Supreme Court judgment carries a citation and a bench. Not one High Court judgment in over 1.26 million carries a citation. You get the text and the case number and nothing you can put in a plaint.

    That is not a defect in the dataset so much as a fact about what is freely available, and it changes the workflow rather than ending it. The corpus is where I find the case and read the reasoning. The citation comes from elsewhere, and it comes before anything is filed.

    The dates need care too. Telangana decision dates in this data run from 23 October 1952 to 27 December 2079. Twelve judgments are dated in the future. The year column in the Andhra Pradesh file tracks ingestion rather than decision and cannot be used for anything.

    Which court binds

    For a matter in Telangana, a Supreme Court judgment binds, the Telangana High Court binds, and the Andhra Pradesh High Court binds only for the period before bifurcation. Bombay and Madras are persuasive, and worth reading, and they are not the same thing. The distinction has to survive into the document.

    The dataset splits along that line almost exactly, which was a pleasant surprise:

      telangana, decided before 01.01.2019          707,308
      andhra-pradesh, decided before 01.01.2019       1,011
      andhra-pradesh, decided 01.01.2019 onwards    259,200

    The in_telangana file is the predecessor court’s whole corpus going back to 1952. The in_andhra-pradesh file is overwhelmingly the reconstituted court at Amaravati. So the default tier applies a date predicate to the AP file alone, and the binding tier comes to 1,043,172 judgments. Every result line is labelled BINDING or persuasive, and a binding search says on its face that the other High Courts were not searched.

    This nearly went wrong in a way worth describing, because it is the most dangerous class of bug in the whole project.

    DuckDB’s regexp_extract(string, pattern) returns the whole match, not the capture group. The build stored in_telangana_judgments where it meant telangana. Every comparison against a bare court name then failed silently. The effect was that 260,766 post-2019 Amaravati judgments sat in the binding tier, labelled BINDING, and the authority ranking collapsed to plain date order.

    Nothing errored. Nothing looked broken. A one-argument mistake quietly relabelled persuasive authority as binding, which in a document going to court is exactly the sort of error you do not get to explain away. The build now passes the group index, and the reader normalises whatever form it finds, so a stale index cannot mislabel authority even if it is rebuilt wrongly.

    Search without a search engine

    The obvious way to search a million judgments is a full-text index. I could not use one, for a reason that is specific and worth explaining, because it shaped the design.

    The environment Claude reaches my machine through is a small sandbox: 2 CPUs, 3 GB of RAM. My workstation reports 32 CPUs. A full scan of the 9.1 GB binding tier takes seconds on the workstation and over three minutes in the sandbox, which is past the timeout on a single call. DuckDB’s full-text extension cannot be installed in that sandbox at all: the proxy variable is malformed for its parser, and with the proxy unset there is no network.

    So an index that needed the extension would have been unreadable by the one reader that most needed it. The answer was plain sorted parquet, built natively on the fast machine, read cheaply by anything.

    Four files:

      cases.parquet      one row per judgment            0.05 GB
      text.parquet       chunks, sorted by case          4.24 GB
      vocab.parquet      words and their ids             0.10 GB
      postings.parquet   (token, case, chunk)            0.91 GB
                                                total    5.31 GB

    Over 1,303,939 judgments, 15,057,895 distinct indexed words, and 397,445,969 postings.

    Two calibration decisions matter more than the structure.

    Minimum word length is 4, not 5. Sale, deed, gift, rent and lien all carry legal phrases. Three-letter words are lost, so lis pendens is found on pendens alone, which is fine because the rarer half of a phrase does the work.

    The commonness cut is 10 per cent, not 1. Words appearing in more than that share of cases are not indexed, because indexing them costs enormously and narrows nothing. The first threshold chosen was 1 per cent. Measured against 17,684 Supreme Court cases:

      possession      5.3%
      registration    1.9%
      performance     1.8%
      adverse         1.6%
      injunction      1.1%
      mortgage        1.0%

    A 1 per cent cut would have excluded every one of them. It would have produced a technically excellent index, of a corpus of property judgments, that could not search for possession, registration, performance, adverse or mortgage. Only 375 words are common enough to exclude at 10 per cent, and when a search hits one it is reported by name, so a search for “part performance” says it searched on performance alone.

    Matching is by proximity, not merely co-occurrence. Postings carry the chunk as well as the case, so intersecting on chunk requires the words to fall within the same passage of roughly 2,000 characters. It does not prove the phrase appears in that order. It is much better than “both words are somewhere in this judgment”, and the phrase still has to be confirmed by reading.

    Three performance facts

    Row group size is the difference between a skip and a scan. At 50,000 rows per group, each group in text.parquet held about 80 MB of text, so fetching 200 scattered cases decompressed most of the file and took 29 seconds. At 1,000 rows a group is under a megabyte and the reader skips almost everything.

    An IN-list of literals is pushed down; a JOIN is not. The same 200 lookups written as a join against a temporary table read the entire file: 0.1 seconds became over 40.

    A warm cache lied to me twice. Verifying a phrase by reading the text costs about 20 seconds cold, however few cases it asks for, because a 4 GB store cannot stay resident in 3 GB of RAM. Two earlier measurements of 2.5 seconds were a warm cache, and they misled the design twice before the proximity approach removed the need to read text at query time at all.

    Where it landed, on 2 threads:

      specific performance   1.02s   8,466 cases
      adverse possession     0.91s
      lis pendens            0.85s
      pattadar pass book     0.92s

    Against over three minutes before any of this.

    One further thing had to be designed rather than discovered. Ordering strictly by authority, a window on “specific performance” returned 400 Supreme Court cases and nothing at all from 11,429 Telangana candidates. Telangana is the court I appear before. Display slots are now shared between courts, allocated smallest tier first so slack flows onward.

    What I still do not trust

    A corpus is only as useful as its own account of where it is weak.

    Two Central Acts cannot be completed from India Code. The Income-tax Act 1961 and the EPF Act 1952. India Code holds no Act-level PDF for them and only a fraction of the sections. Both are fetched separately.

    The Hindu Succession (Andhra Pradesh Amendment) Act 1986 matters for coparcenary devolution before 9 September 2005, and the only copy I have is from PRS Legislative Research, which prints its own disclaimer that the text is unverified. It is deliberately kept off the Act surface and findable only in my own-work index. The real text has to come from the Law Department before it is cited.

    Every HMDA document arrived over an unvalidated TLS connection. All 75 are stamped tls=unverified, because hmda.gov.in’s certificate chain does not validate. They are usable and they are flagged, and any one of them is checked against the browser copy before it is cited.

    OCR misreads digits. 522 scanned PDFs, 6,738 pages, English and Telugu, banded 222 high confidence, 193 medium, 107 low. A document number came back as NO,P 2418/2013-14. Any survey number, extent or consideration taken from OCR text is checked against the original PDF. Results drawn from OCR print a warning saying so. And the opening pages of a registered deed are the stamp paper, which OCRs as ornament noise, so an OCR’d deed is judged by its body and not its first lines.

    Some sources cannot be harvested at all. The CCLA site renders a page header and stops: viewActs.do, viewGO.do and viewCirculars.do each return two links and no table. That is not a selector problem, the pages are empty. And goir.telangana.gov.in is an ASP.NET WebForms application with view-state and cascading postbacks, where a result set only exists after a POST carrying the view-state the server has just issued. A listing-page harvester cannot touch it.

    A naming rule learned the hard way. A document’s title becomes its act name, and lookups match that name loosely. A document titled “Registration Rules, Telangana — rules under the Registration Act, 1908” shadowed the Registration Act itself, so asking for section 49 of the Registration Act returned rule 49 instead of section 49, which is the provision on the effect of non-registration. A title must never contain another instrument’s name.

    And one Act answers twice, by design. HMDA section 5 exists in the corpus in two forms: the Act as originally enacted, naming APIIC, APHB and APSRTC, hand-read by me from printed pages; and the India Code text as adapted for Telangana by G.O.Ms.No.45, Law (F) Department, dated 1 June 2016, naming TSIIC, the Telangana Housing Board and TSTRANSCO. Both are correct. For the composition of the Executive Committee as it stands today, the adapted text governs.

    What this is actually for

    It is not a product and I am not proposing that anyone else run one. It is a tool with a known shape, whose weaknesses are written down where I can see them, which answers in about a second, and which does not stop working if a subscription lapses or a website is redesigned.

    The thing I did not expect was how much of the work would be auditing rather than building. The scraping was a weekend. The gates, the calibration, the gap analysis, the five defects in the recovery pass and the one-argument bug that mislabelled a quarter of a million judgments as binding — that was the actual project.

    Which brings it back to HMDA section 5. It was in the corpus the whole time. The lesson is not that the pipeline was bad. It is that a lookup which answers “no such section” and a lookup which answers “here is section 5” can both be produced by a database that holds the same bytes, and the only thing standing between them is whether anyone checked.


    Glossary

    This post has two audiences, and each will find half of it obvious. The terms below are defined in the order they appear, on the assumption that no reader knows both halves.

    Act surface — my term for the set of files a section lookup searches, as distinct from the full-text library. A document promoted to the Act surface can be asked for by section number. One left in the library can only be found by searching its words.

    Parquet — a file format for storing tables in columns rather than rows, compressed, with statistics recorded for blocks of rows. A reader can consult those statistics and skip blocks that cannot contain what it wants, without decompressing them.

    Row group — a block of rows inside a parquet file, and the unit that a reader skips or reads. Their size is a design decision, discussed above.

    DuckDB — a database engine that runs inside your program rather than as a server, and reads parquet files directly from disk. No installation to maintain, no daemon running.

    Predicate pushdown — the behaviour that makes the above work: the filter is handed down to the file reader so it can skip data, instead of the reader returning everything and the filter discarding most of it afterwards. An IN-list of literal values is pushed down. A join against another table generally is not.

    Full-text index / FTS — the conventional machinery for searching text at speed, usually a database extension. Not used here, for the sandbox reasons set out above.

    Vocabulary and postings — the two halves of any word index. The vocabulary maps each word to a number. The postings list records, for each word number, where it occurs. Searching is intersecting postings lists.

    Posting — one entry in that list. Here each posting is a triple of word, case and chunk, which is what makes proximity matching possible.

    Chunk — a passage of a judgment, roughly 2,000 characters. Judgments are stored in chunks so that “these two words appear in the same chunk” can stand in for “these two words appear near each other”.

    Proximity matching — requiring search terms to fall within the same chunk, rather than merely somewhere in the same document. It does not prove the words appear as a phrase in that order.

    MINLEN — the shortest word the index will store. Set to 4 here.

    Commonness cut — the share of documents above which a word is too common to be worth indexing. Set to 10 per cent here, for the reasons measured above.

    OCR — optical character recognition, deriving text from a scanned image. Reliable for prose, unreliable for digits, which is why numbers taken from OCR are checked against the original.

    Text layer — the machine-readable text embedded in a PDF. A PDF produced from a word processor has a good one. A PDF that is a photograph of a page has none, and needs OCR.

    Marginal note — a section heading printed in the margin beside the body text rather than above it. The cause of the HMDA failure: in the text layer the marginal notes interleave with the sentences.

    Splitter — the code that divides a statute into its sections. Most of the failures described here are splitter failures.

    Page group — the fallback when a document cannot be split reliably: it is stored as groups of pages, flagged as unsplit, rather than given section numbers that might be wrong.

    Capture ratio — the proportion of a document’s text that a split accounts for. Below 92 per cent the split is rejected, so no document can silently lose text.

    Digit density — the proportion of characters in a block that are digits. Prose runs 3 to 4 per cent, schedules 24 per cent and up.

    Harvester — the script that fetches documents from government websites, driven by a manifest describing each source, rather than a separate scraper per site.

    Manifest — the configuration file listing each source, its pages, and how to treat what it returns.

    G.O. — Government Order. A departmental instrument. G.O.Ms. is an Ordinary Order; the number and date identify it.

    India Code — the Government of India’s official repository of Central and State legislation.

    Bifurcation — the division of Andhra Pradesh on 2 June 2014, creating Telangana. An Andhra Pradesh Act from before that date continues to apply in Telangana; one from after it does not.

    Binding and persuasive — a judgment of a court above you in your own hierarchy binds. A judgment of a court of equal standing elsewhere is persuasive: worth reading, worth citing, but it does not compel a result.

    Pattadar pass book — the Telangana land record document evidencing a cultivator’s rights. Used above as a search example because it is a phrase of exactly the shape this index handles well.

    Coparcenary — in Hindu law, the body of family members who take an interest in ancestral property by birth. Relevant here because devolution before 9 September 2005 turns on statutory amendments that must be sourced accurately.

    Sandbox — the constrained environment the AI assistant reaches my machine through: 2 CPUs, 3 GB of RAM, restricted network. Several design decisions exist only because of it.

    TLS validation — the check that a website’s certificate chains to a trusted authority. tls=unverified on a stored document means the download was made without that check succeeding, and the document should be confirmed against the browser copy before it is relied upon.

  • A parse error, a stalled upgrade, and fifteen years of silence

    A parse error, a stalled upgrade, and fifteen years of silence

    I knew this site was broken. I did not know for how long, or why, and for years I did not look. It sat at techblog.viveksanghi.com returning nothing, and every year that passed made it a slightly larger thing to open.

    When I finally opened it, the server turned out to have been keeping a precise record of what happened.

    I did the work over one evening with Claude, which matters to how this reads. I made the decisions and ran every command on my own server; the diagnosis, the scripts and several confident wrong turns came from the model. The wrong turns are in here too, because they were the useful part. Tech is a hobby for me. Law is what earns my living, and a fifteen-year-old broken WordPress had long since stopped being a thing I could justify an evening on. Having something that would grind through log files and SQL dumps without getting bored changed that arithmetic.

    What the server was saying

    The first question was whether anything was alive at all. The domain resolved to my DreamHost IP, same as my other sites, so DNS was fine. HTTPS failed on a certificate error. Over plain HTTP I got a 301 to the www hostname, then a 500 Internal Server Error with an empty response body.

    An empty 500 is a particular kind of unhelpful. No error on the page, no stack trace, nothing to search for. It means PHP died before producing output, with display_errors off, which on a production host it should be.

    The useful clue came from the access log rather than the error log:

    2026-09-02 21:24:28   200   /favicon.ico

    A 200. Static files were being served. That one line rules out most of what an empty 500 can mean. Apache was healthy, the virtual host was configured, the document root pointed at the right folder. Only PHP was dying.

    Which meant anything on the site that was not PHP could still be read. So we asked for the file every WordPress install ships and nobody ever deletes:

    curl http://techblog.viveksanghi.com/readme.html
    Version 3.1.2
    Semantic Personal Publishing Platform

    WordPress 3.1.2, released April 2011.

    The one-line cause

    The error log had been recording the same entry for years:

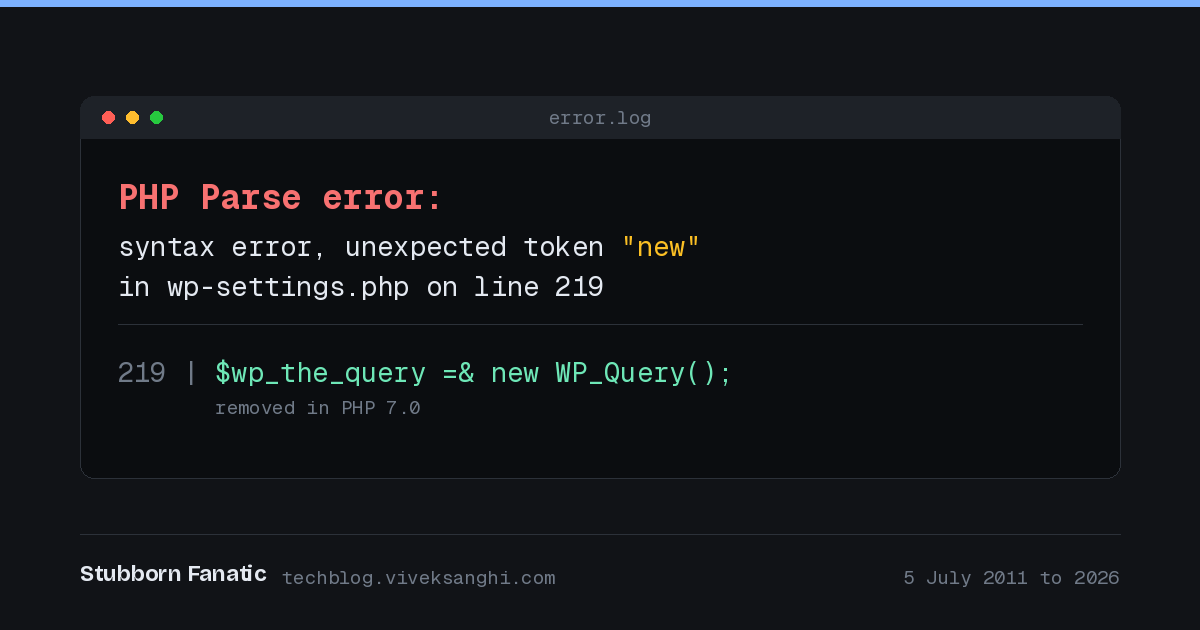
    [techblog.viveksanghi.com] [warn] mod_fcgid: stderr: PHP Parse error:
    syntax error, unexpected token "new" in
    /home/viveksanghi/techblog.viveksanghi.com/wp-settings.php on line 219

    Line 219 of WordPress 3.1.2 reads:

    $wp_the_query =& new WP_Query();

    That =& is assignment by reference to a newly created object. It was correct in PHP 4, where objects were copied on assignment and the reference avoided the copy. PHP 5 made objects handle-based and the construction became pointless. It was deprecated in PHP 5.3 and removed in PHP 7.0.

    Removed, not deprecated. In PHP 7 and later this is not a warning or a runtime error. It is a parse error. PHP refuses to compile the file, so nothing in it executes, no error handler runs, no output is produced, and Apache has nothing to return but a bare 500.

    The site did not break from anything I did. It broke when DreamHost moved past PHP 5, and it has been serving 500s to search engines and bots ever since.

    Could it be patched? The construction appears 252 times across WordPress core. PHP stops at the first one, but fixing that line only exposes the next. This is not a bug you repair. It is a language incompatibility, and the only answer is a newer WordPress.

    The timestamp in the root directory

    Sitting in the web root was a file called .maintenance, containing one line:

    <?php $upgrading = 1309848013; ?>

    WordPress writes that file when it begins a core update and deletes it when the update finishes. This one was never deleted.

    That Unix timestamp is 05/07/2011, 06:40 UTC.

    WordPress 3.2 was released on 04/07/2011. Alongside .maintenance were two directories in wp-content called wordpress-3.tmp and wordpress-31.tmp, the staging folders the updater uses while unpacking.

    So: the day after 3.2 came out, I clicked update. It stalled. It left the lock file, the temp directories, and a site still running 3.1.2.

    The lock file did no harm. WordPress ignores a .maintenance older than ten minutes, a sensible piece of defensive design and the reason the site kept serving afterwards. But it dates the incident to the minute.

    What the logs cannot tell you is what the site looked like when it stopped.

    It was running Grid Focus, a theme I had modified by hand over several years until not much of the original remained, with a stack of plugins I had chosen one at a time. The update took it down. I troubleshot for a while. Then life happened, and I lost interest the way you do when a thing stops being fun and starts being a chore.

    So I let it sit. Somewhere between 2020 and 2022 I paid a freelancer on Fiverr to bring it back, and for a while it worked. That did not last either.

    Both theme folders were still on the server when I finally went looking. grid_focus_public and gridfocus-v1.5.1b, sitting among fifty other themes I had collected and forgotten, exactly where I left them in 2011.

    Five years of nobody noticing

    The site did not go down in 2011. It went stale in 2011 and died some years later when PHP moved on. The first half is provable.

    An old wp-dbmanager install had been taking weekly database backups and leaving them in wp-content. There were 134 of them, 2.7 GB in total, running from 29/05/2011 to 31/07/2016.

    Comparing the oldest against the newest, by table:

    techblog_..._20110612.sql   posts: 274,916 bytes   comments: 370,174 bytes
    techblog_..._20160731.sql   posts: 274,916 bytes   comments: 370,174 bytes

    Byte for byte identical. Not a single post or comment changed between June 2011 and July 2016. The blog stopped in 2011 and the backups kept copying the same corpse every Sunday until they stopped too.

    But the dumps grew from 1.4 MB to 37 MB over those years. Something was expanding. Breaking the 2016 file down by table:

    12,549,505  wp_usermeta
       370,174  wp_comments
       342,650  wp_options
       274,916  wp_posts
        79,785  wp_postmeta

    Twelve and a half megabytes of user metadata against 275 KB of actual writing, reaching about 35 MB by the final backups. Open registration on an unpatched WordPress 3.1.2, and five years of bots signing up. The comments stayed clean, which I put down to Akismet and the captcha plugin, though I cannot prove that from the data. Nothing at all was guarding the registration form.

    Ninety per cent of my database was junk accounts.

    Deciding not to repair

    Reviving the 3.1.2 install was never really available. There is no supported upgrade path across fifteen years, and the parse error fires before WordPress prints a byte, so I could not reach an admin screen to start one.

    Rebuilding felt right for a less technical reason. The install carried 44 plugins and 51 themes. Among the plugins were disable-wordpress-core-update and disable-wordpress-plugin-updates, which explains a good deal about why it was still on 3.1.2. Copies of wordpress-28.zip through wordpress-284.zip sat in wp-content, publicly readable. There was a forum directory, empty, and two bbPress integration plugins pointing at it.

    A WordPress 3.1.2 install had been exposed to the open internet for roughly eight years before PHP killed it, and that version has a long published list of vulnerabilities. There is an irony worth sitting with: the parse error that took the site down has probably been protecting it since about 2019.

    So: current WordPress, content carried across, nothing else.

    Getting the content out

    The live database was reachable but not trustworthy, and I had 134 dumps provably unchanged since 2011. We took the last one and parsed it directly rather than restoring it anywhere.

    Two things came out of that which looking at the site would never have shown.

    The comments were duplicated. The table held 840. After normalising whitespace and stripping tags, only 606 were distinct. 234 were exact duplicates of another comment on the same post by the same author, each pair differing only in whether the
    tags had survived:

    id=7    2006-09-06 16:54   'Thanks for viewing my Blog. Well... I must say...'
    id=505  2006-09-06 11:24   'Thanks for viewing my Blog. Well... I must say...'

    The second copies sit in a contiguous block of IDs above 500. The database is called techblog_blogger and the install had a blogger-blogspot-redirect plugin. A Blogger import run twice in 2006, once preserving HTML and once stripping it. Twenty years, and I never noticed, because on the page a duplicate comment just looks like somebody posting twice.

    The spam was not where anyone expected. Given the state of the usermeta table, the assumption was that comments would be full of pharma and casino links. A pattern search for the usual vocabulary returned zero matches. The volume by year decays the way real traffic does, 571 in 2006, 208 in 2007, then single and double digits as the blog went quiet, rather than flooding the way a farmed table does.

    The first attempt to find spam scored comments by link density. On a blog about Blogger and WordPress hacks that is a terrible signal, and it flagged 43 comments, most of them my own replies containing four or five links to code examples. Claude had produced that heuristic, run it, looked at the output and thrown it away unprompted, which was the right call and not one I would have caught if it had not shown me the list.

    The second pass went by author name and destination domain and found the real thing: thirteen keyword-anchor link drops, the kind where the author name is the product. “Mens Suit” linking to a suit retailer. “Website Design Atlanta”, three times. “beats for sale”. “laptop battery”. Short, on-topic enough, easy to approve by accident in 2010.

    That left 593 comments, all genuine, threading intact.

    There was also a post dated 26/12/2020 in a database dumped in 2016. A draft whose post_date carried a mistyped year, its post_modified correctly reading 27/12/2010. It had been sitting ten years in the future for a decade.

    What the rehearsal caught

    Rather than trust the import, we rehearsed it: MariaDB and WP-CLI in a throwaway container, the same WordPress version, a replica of the uploads folder, the real import file.

    Every expected number came back right except one. Attachments came out as zero instead of eighteen.

    The WordPress importer does not simply create attachment records. For each attachment it downloads the file from the URL in wp:attachment_url. In the container that URL was unreachable, so every attachment failed silently.

    On a real server it is worse than a clean failure. The URL points at the site being restored, over HTTPS, at a moment when the certificate has not been issued. And if the download does succeed, it writes a second copy of every file beside the ones already sitting in wp-content/uploads.

    The fix is to tell it not to:

    wp import export.xml --authors=create --skip=attachment

    and then register the files already on disk, in place:

    find wp-content/uploads -type f \( -iname '*.jpg' -o -iname '*.gif' \) \
      | grep -vE -- '-[0-9]+x[0-9]+\.[A-Za-z]+$' \
      | while read -r f; do wp media import "$f" --skip-copy; done

    The grep -v matters. Of 56 files in the uploads folder, 36 were WordPress’s own generated thumbnails. Without that filter every -150x150 crop becomes its own media library entry.

    Nobody would have found this by reading the script. It appeared only by running the whole thing end to end against a real database.

    Four ways the deploy script was wrong

    This is the part I would not have predicted before the evening started. The script that rebuilt the site was written for me to paste into an SSH session, and it had to be fixed four times before it ran clean. Every failure was caught by the script’s own preflight, before anything on my server was touched.

    getent does not exist on DreamHost’s shell. The DNS check used it. The script would have aborted in preflight with a confusing error. Replaced with a PHP lookup, since PHP is guaranteed present there.

    pipefail and head do not mix. The script ran wp --info | head -3. head closes the pipe after three lines, wp gets SIGPIPE and exits 141, and set -o pipefail with set -e turns that into a silent abort. The three lines of output on my screen were the last thing the script printed before killing itself, and the failure looked like nothing at all.

    A $ in a password. My admin password contained $4. Inside double quotes bash expands that as a positional parameter, which does not exist, and set -u correctly aborted. The config block now uses single quotes.

    --raw wrote an undefined constant. This one actually reached my server. The script ran wp config set WP_AUTO_UPDATE_CORE minor --raw, which writes define('WP_AUTO_UPDATE_CORE', minor); without quotes. In PHP 8 an undefined constant is a fatal error, so WordPress could not load at all, and the script reported it as “cannot reach the database” — which was wrong and sent me looking in the wrong place.

    There was a fifth, structural, caught before I ran anything: the original script tested the database connection after renaming my site directory. If the database had been unreachable, it would have moved my entire site aside and then died. That ordering was reversed so every destructive step sits behind a check that has already passed.

    I record these because the honest version of “an AI helped me fix my site” includes the four times it handed me something broken. What made it work was not that the output was right first time. It was that each failure was cheap, legible, and caught before it cost anything.

    The redirect loop I caused myself

    With WordPress installed and content imported, the site returned a redirect loop. techblog.viveksanghi.com redirected to www.techblog.viveksanghi.com, which redirected straight back, forever.

    We assumed the host was misconfigured. I opened a support ticket saying so. One command showed we were half wrong:

    curl -sI http://techblog.viveksanghi.com/readme.html      → 301
    curl -sI http://www.techblog.viveksanghi.com/readme.html  → 200 OK

    A static file that exists on disk gets redirected at the bare hostname and served at www. That first redirect happens above .htaccess, in the host’s virtual host configuration, and nothing on my side could override it. That half was DreamHost’s, and they removed it inside a couple of hours when asked properly.

    The second redirect was mine. Static files at www served fine and only WordPress-handled paths bounced. That is redirect_canonical doing its job, because siteurl and home were set to the bare hostname while the server was serving www. Each half behaved correctly. Together they were an infinite loop.

    Testing a static file rather than the homepage is what separated them. On the homepage both redirects are in play and the trace tells you nothing about which layer owns which. I cancelled the first ticket and filed a more accurate one.

    What I would tell someone with a site in this state

    Test a static file first. Whether readme.html serves tells you in one request whether the web server is broken or only PHP is. Almost everything that followed came out of that one 200.

    The error log is the whole answer, and it is not in the panel. The hosting control panel showed access logs and traffic graphs for days. The actual parse error, repeating identically for years, was in a file on disk.

    Check whether your content changed before you value your backups. 134 weekly backups sound like excellent hygiene. Comparing the first against the last showed 134 copies of the same 2011 content, with only the spam growing. Backup count measures nothing.

    Rehearse the restore. A throwaway database and a full dry run took under an hour and caught a defect that would have cost the entire media library, silently, with a success message.

    Suspect your own configuration before your host’s. I was three quarters of the way to blaming DreamHost for a redirect loop I had created myself.

    If you are working with a model, make it show you its output, not just its conclusions. Every one of the four script defects and the bad spam heuristic surfaced because something got printed and looked wrong. None of them surfaced from reading the code.

    The site is back. Seventy-five posts, 17/04/2006 to 25/05/2011, and 593 comments, on WordPress 7.1 with a clean database and no plugins carried across.

    Sixty-eight images in the older posts still point at photos1.blogger.com and the bp1 to bp3 hosts, which Google retired years ago. Those have been broken far longer than the site was, and there is nothing left to restore them from. I am inclined to leave them, with a note. A blog that ran from 2006 should be allowed to show its age somewhere.

  • Welcome to the new location of Stubborn Fanatic

    Hello All,

    I have successfully redirected stubborn-fanatic.blogspot.com to techblog.viveksanghi.com. The new home for this blog.

    Those of you who were looking at my blogspot template for design ideas will be unable to do so any more. However I can send you my blogspot template’s full code for a nominal payment of $20 via paypal only. If you are interested, please contact me using this link for further instructions.